01
Sieve
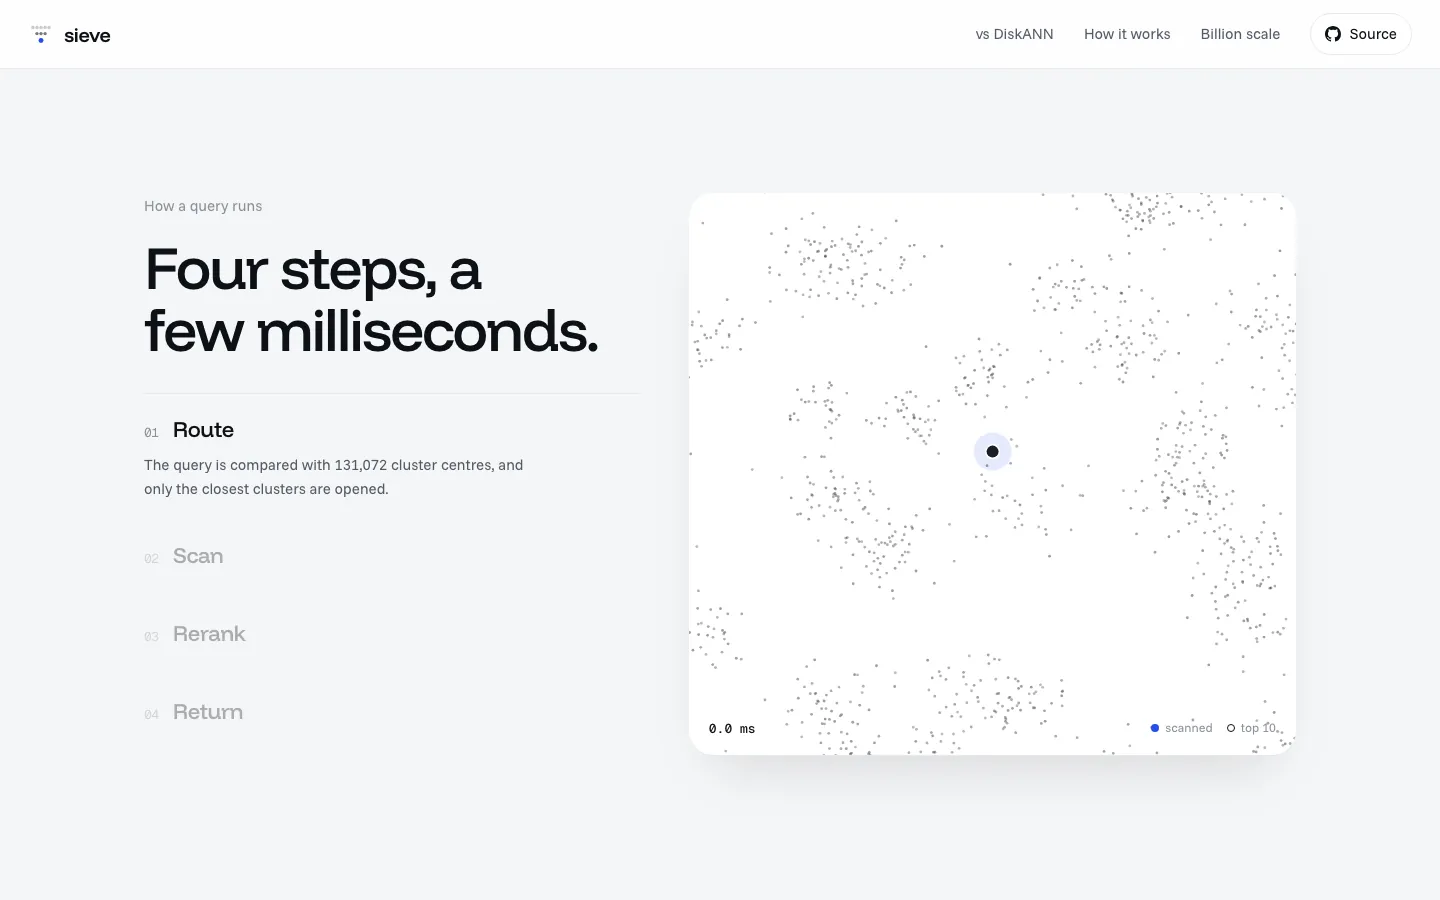
A vector search engine written from scratch in Rust: a billion vectors, searched on one laptop.
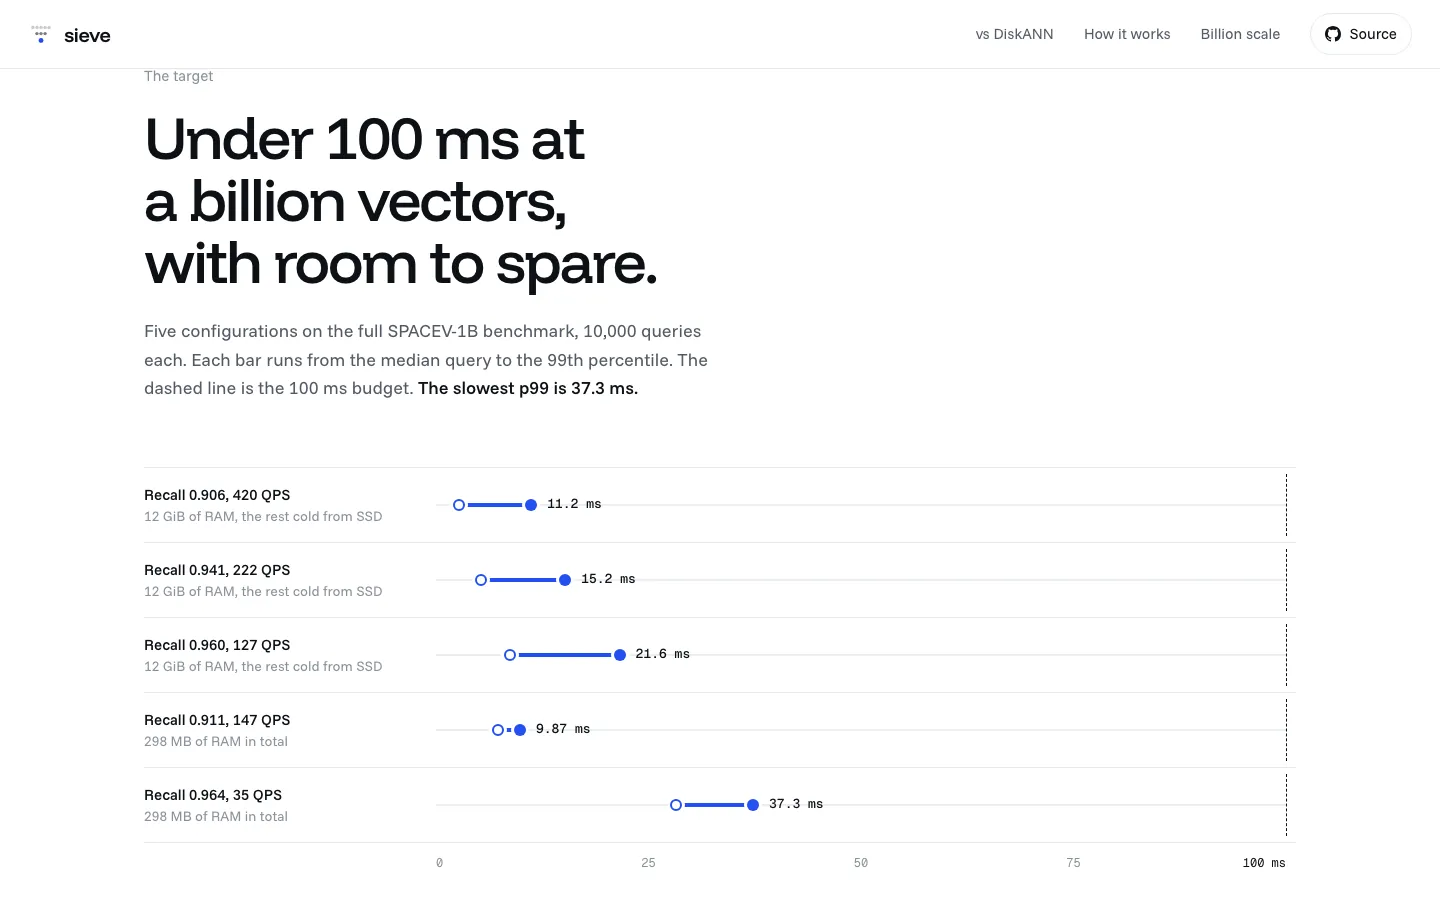
113.5MPassages, One 24 GB Laptop
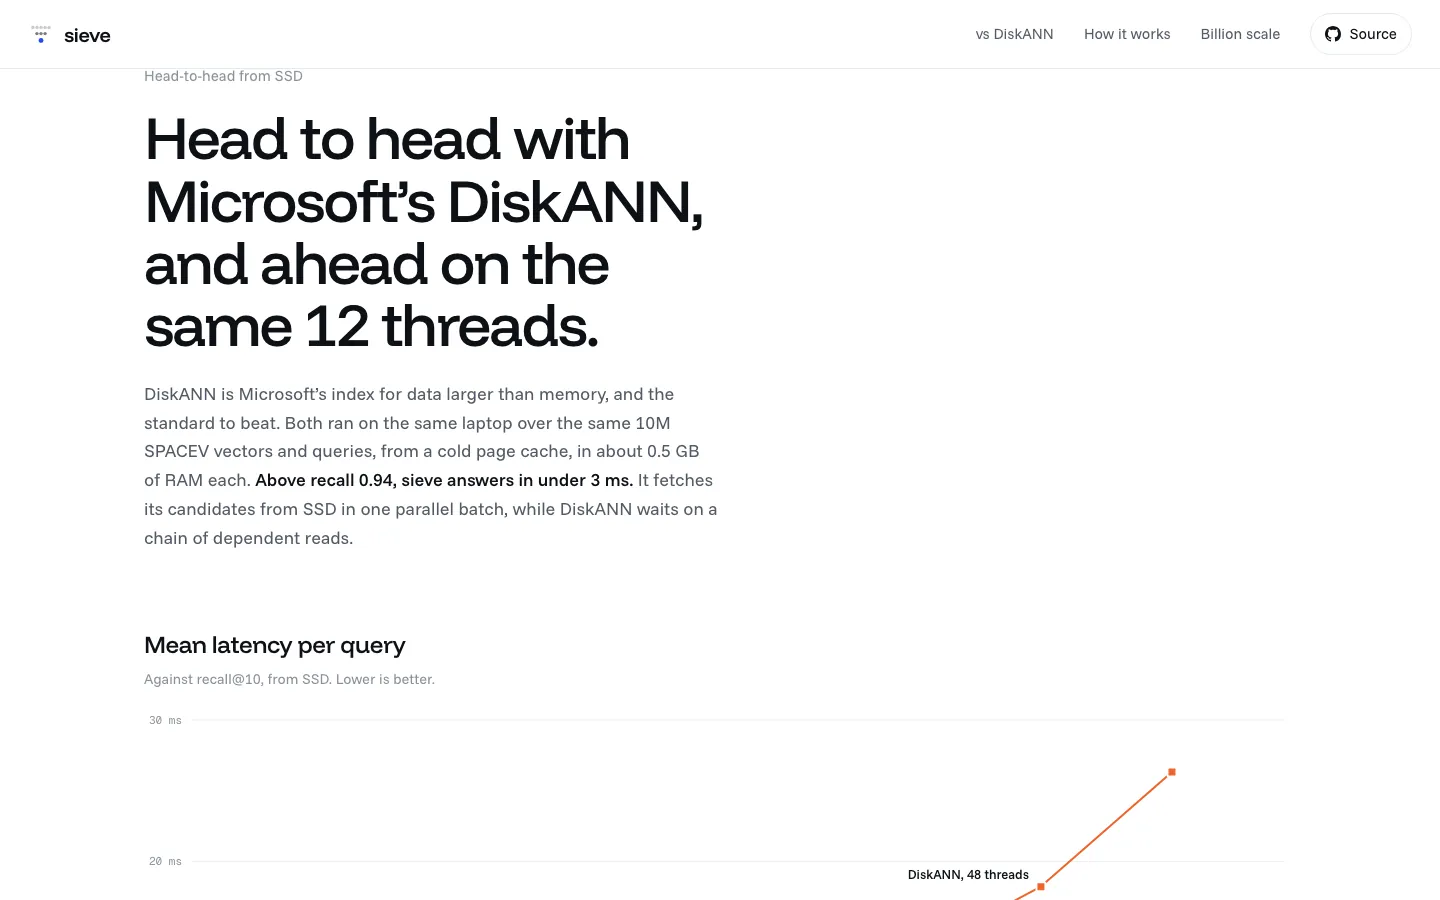
0.909R@10 at 4.8 ms p50
420 QPS1B Vectors, R@10 0.906
225 MBRAM, Everything on SSD
Full-stack engineer across backend, infrastructure and the product on top. Previously JP Morgan Chase. Stellar SCF grantee.
I build things end to end: the idea, the system underneath it, and the part people actually touch.
The subject keeps changing. So far it has been developer tools, payments, privacy, language learning and research, sometimes alone and sometimes inside a large bank. The habit stays the same: understand the problem properly, build the smallest thing that really solves it, then keep at it until it holds up with real people using it.
A vector search engine written from scratch in Rust: a billion vectors, searched on one laptop.
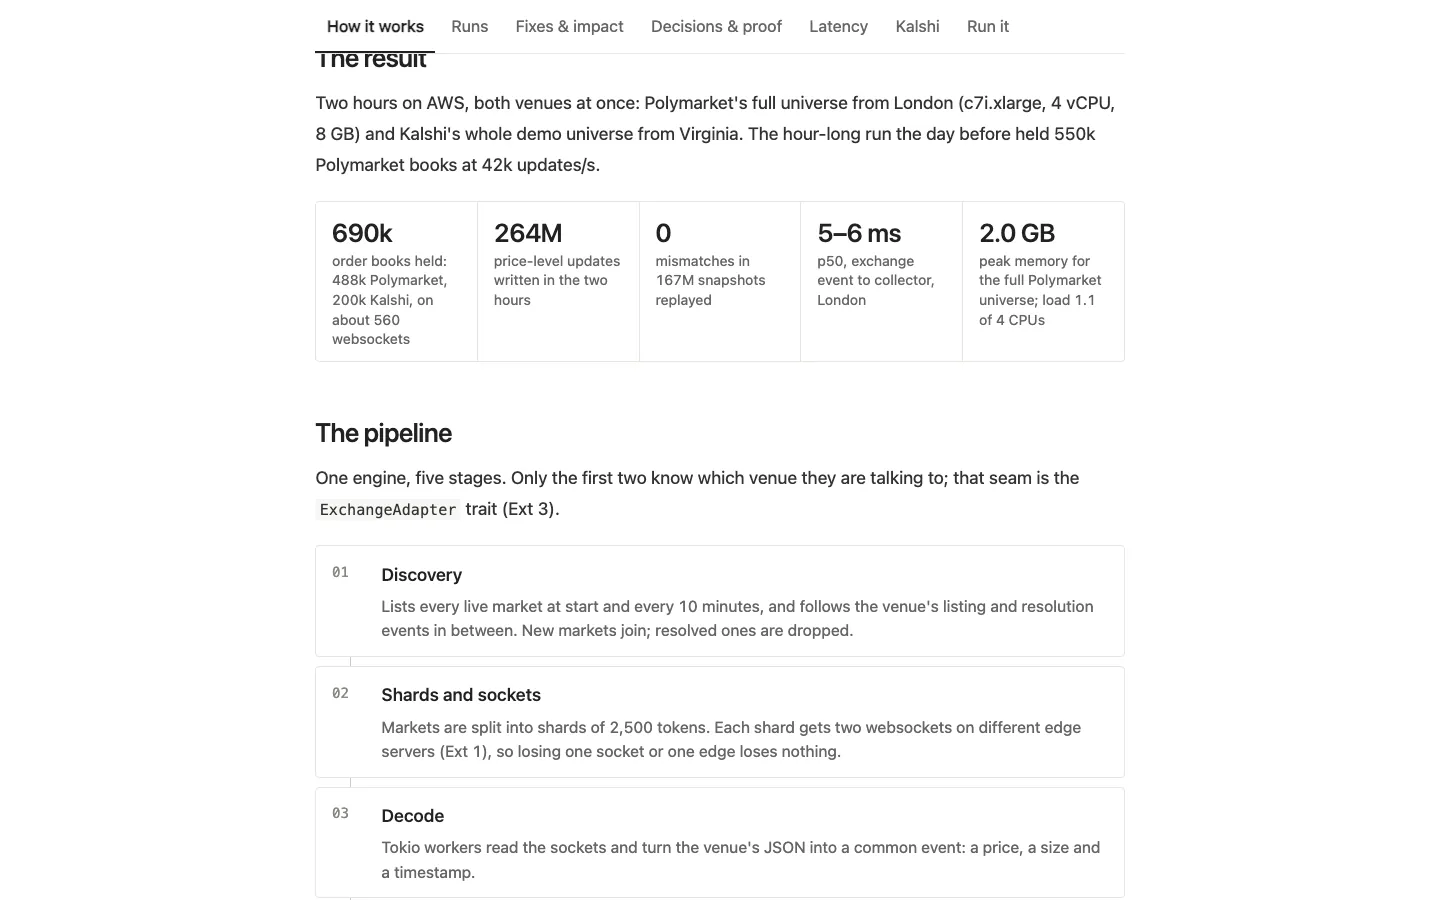
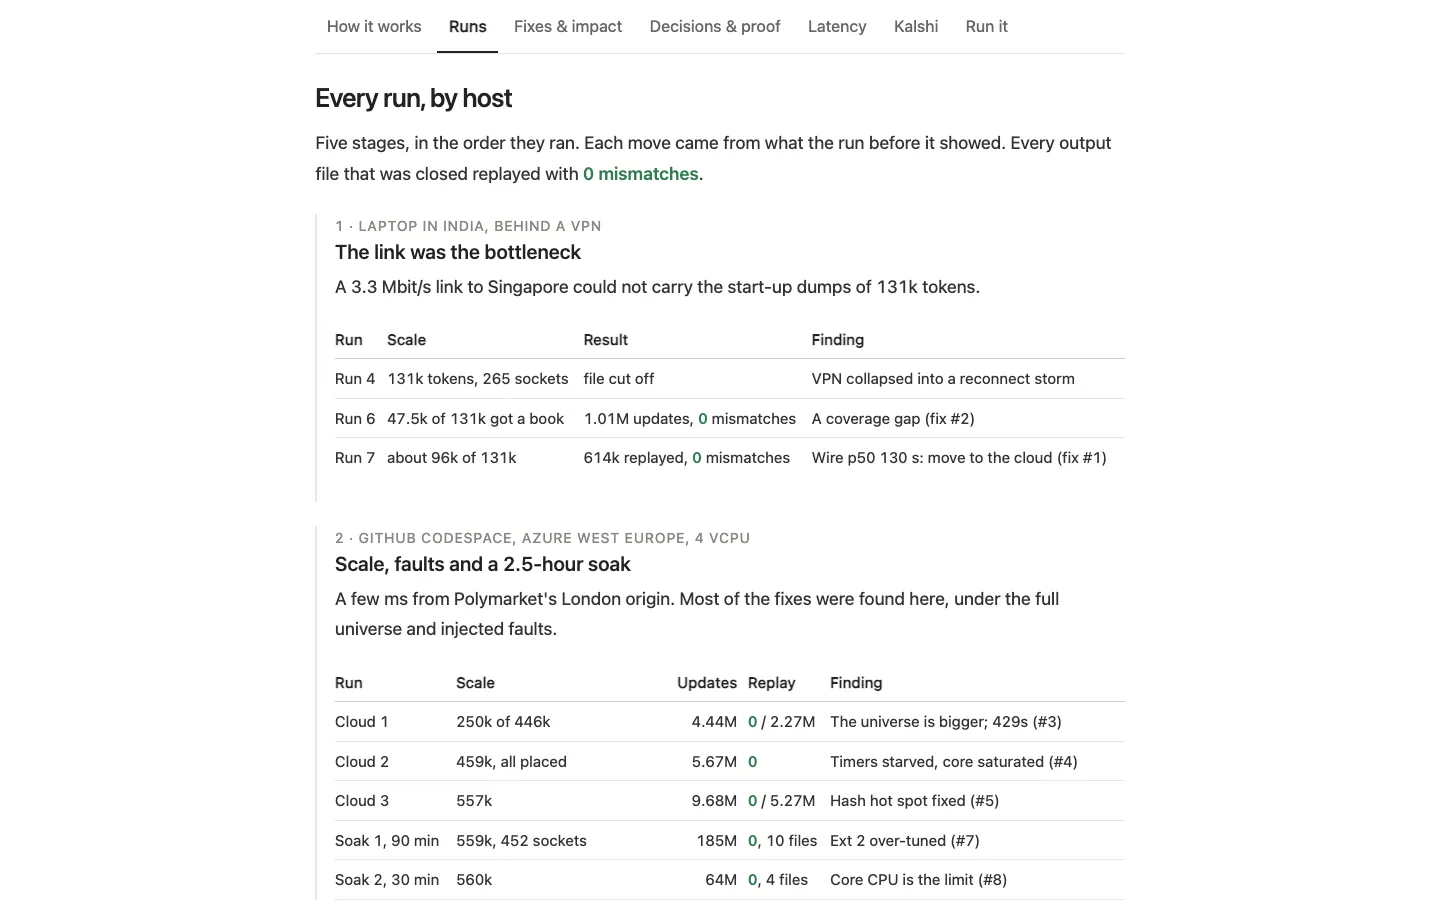
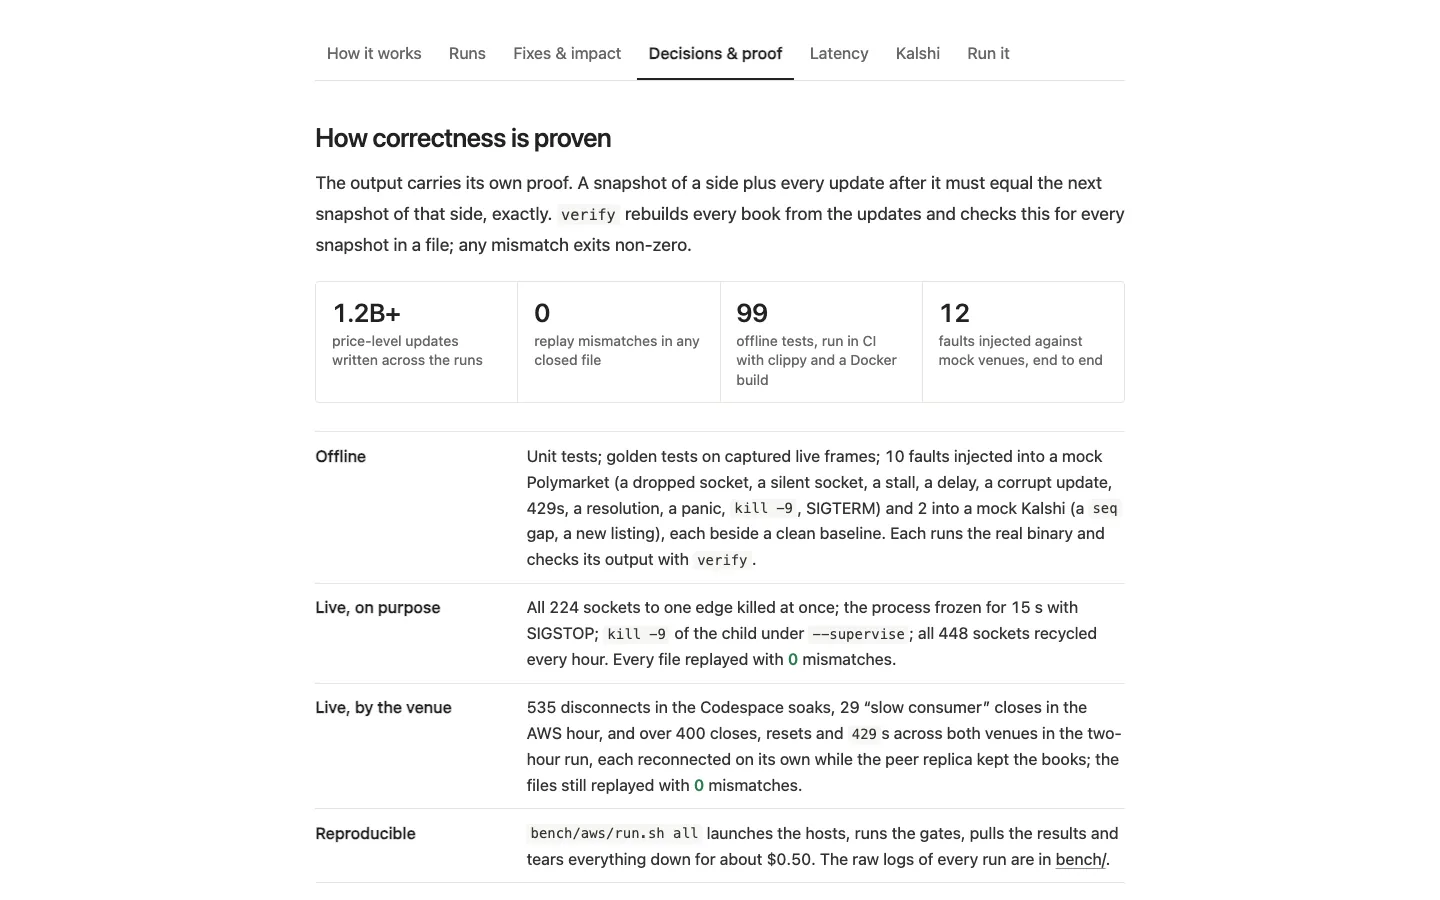
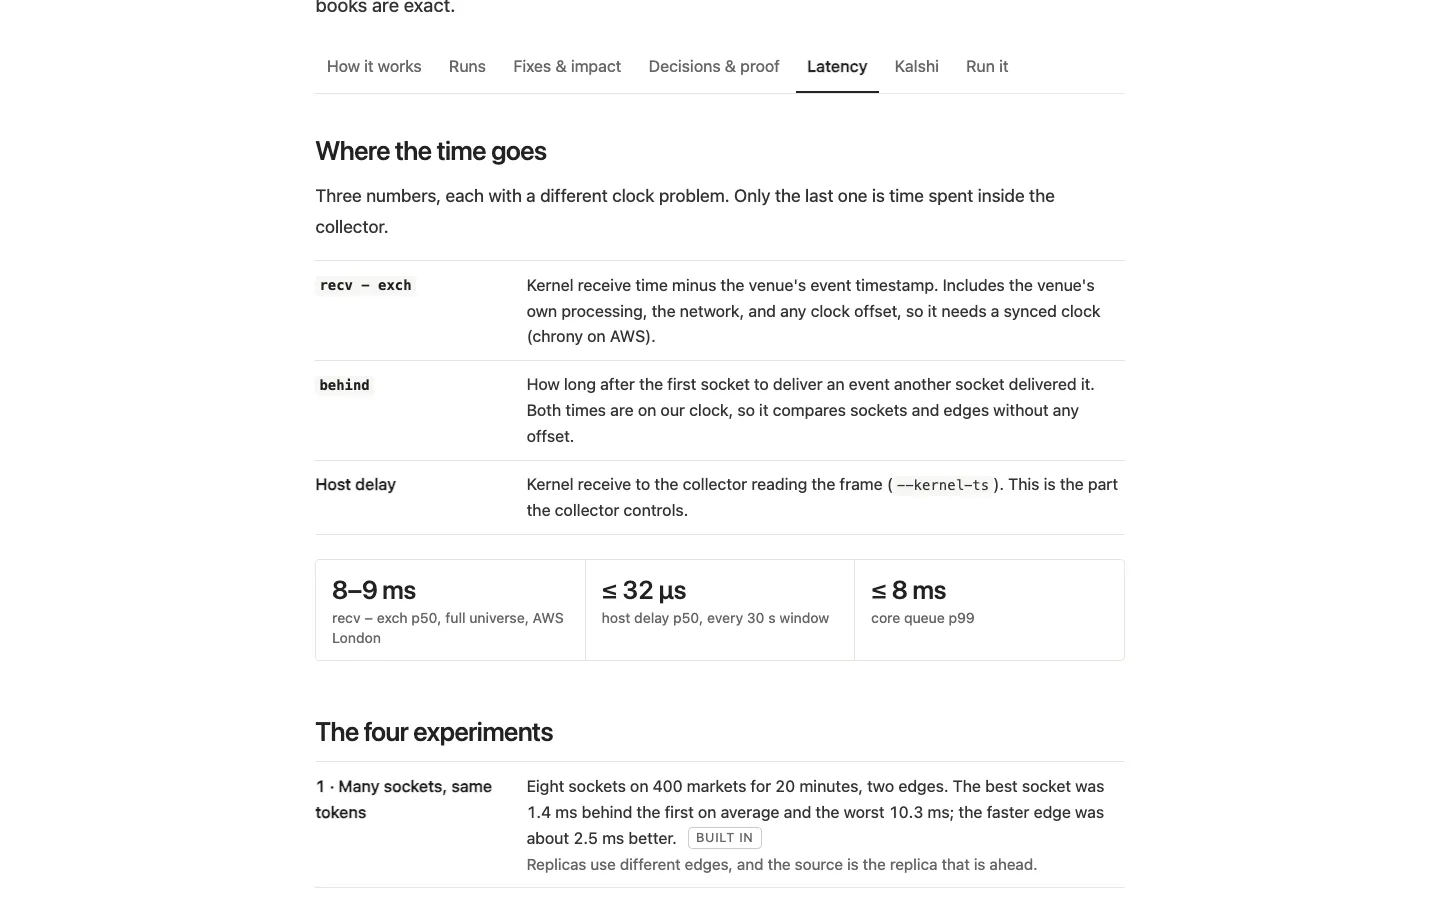
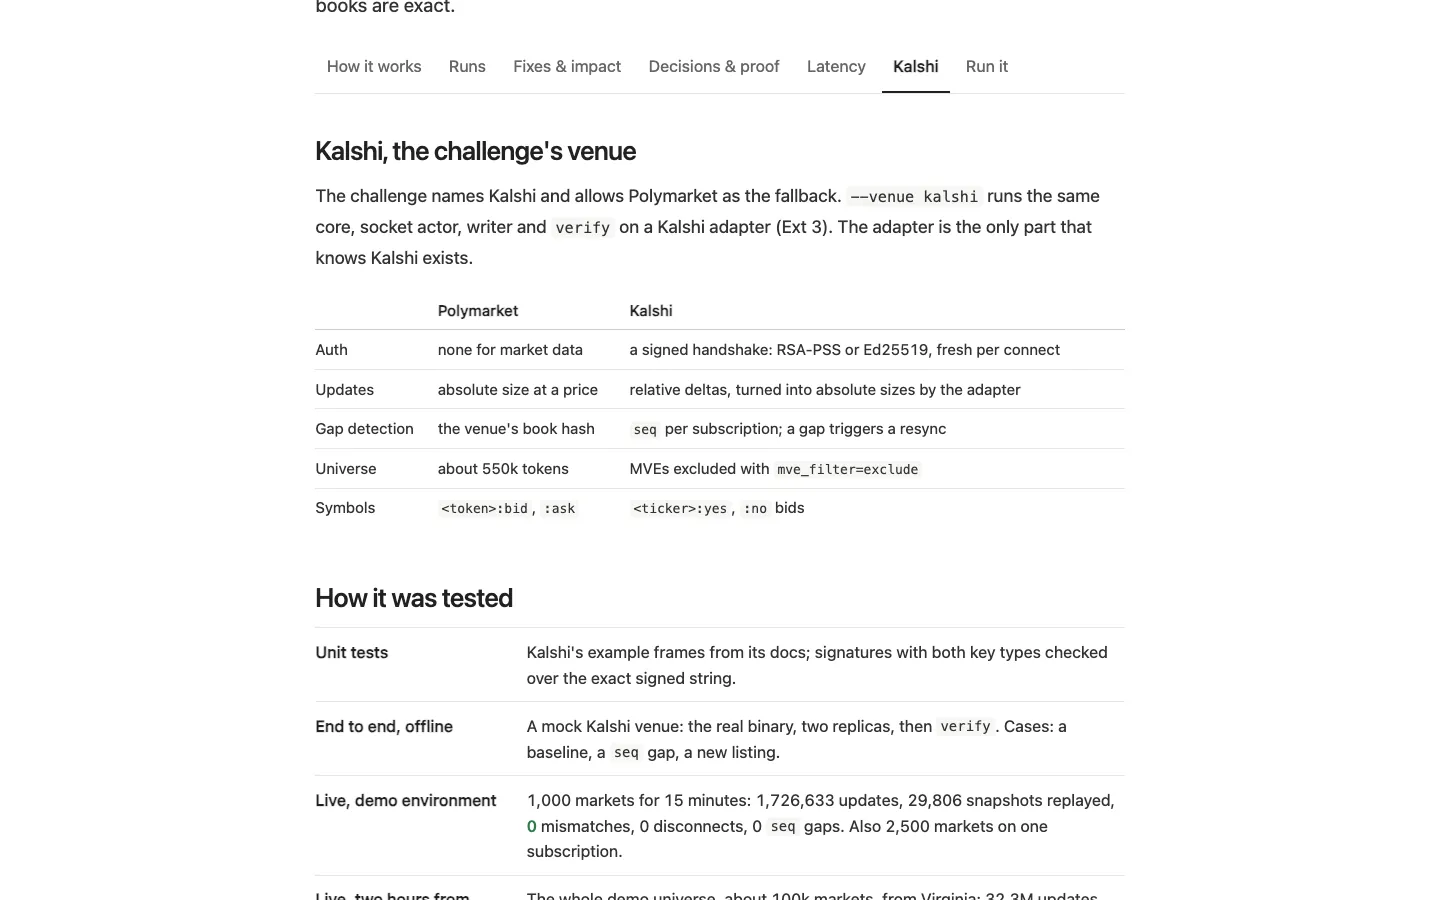
A Rust order-book collector for Kalshi and Polymarket that keeps every book exact.
Local inference vs. the browser compositor: why GPU-heavy pages stutter while a model reads.


A shared, live world model for parallel coding agents, kept in one graph.
The loop that makes an agent's "done" something it has to prove, not just say.
The organizational control plane for agents that hold money, now on C# and .NET 8.
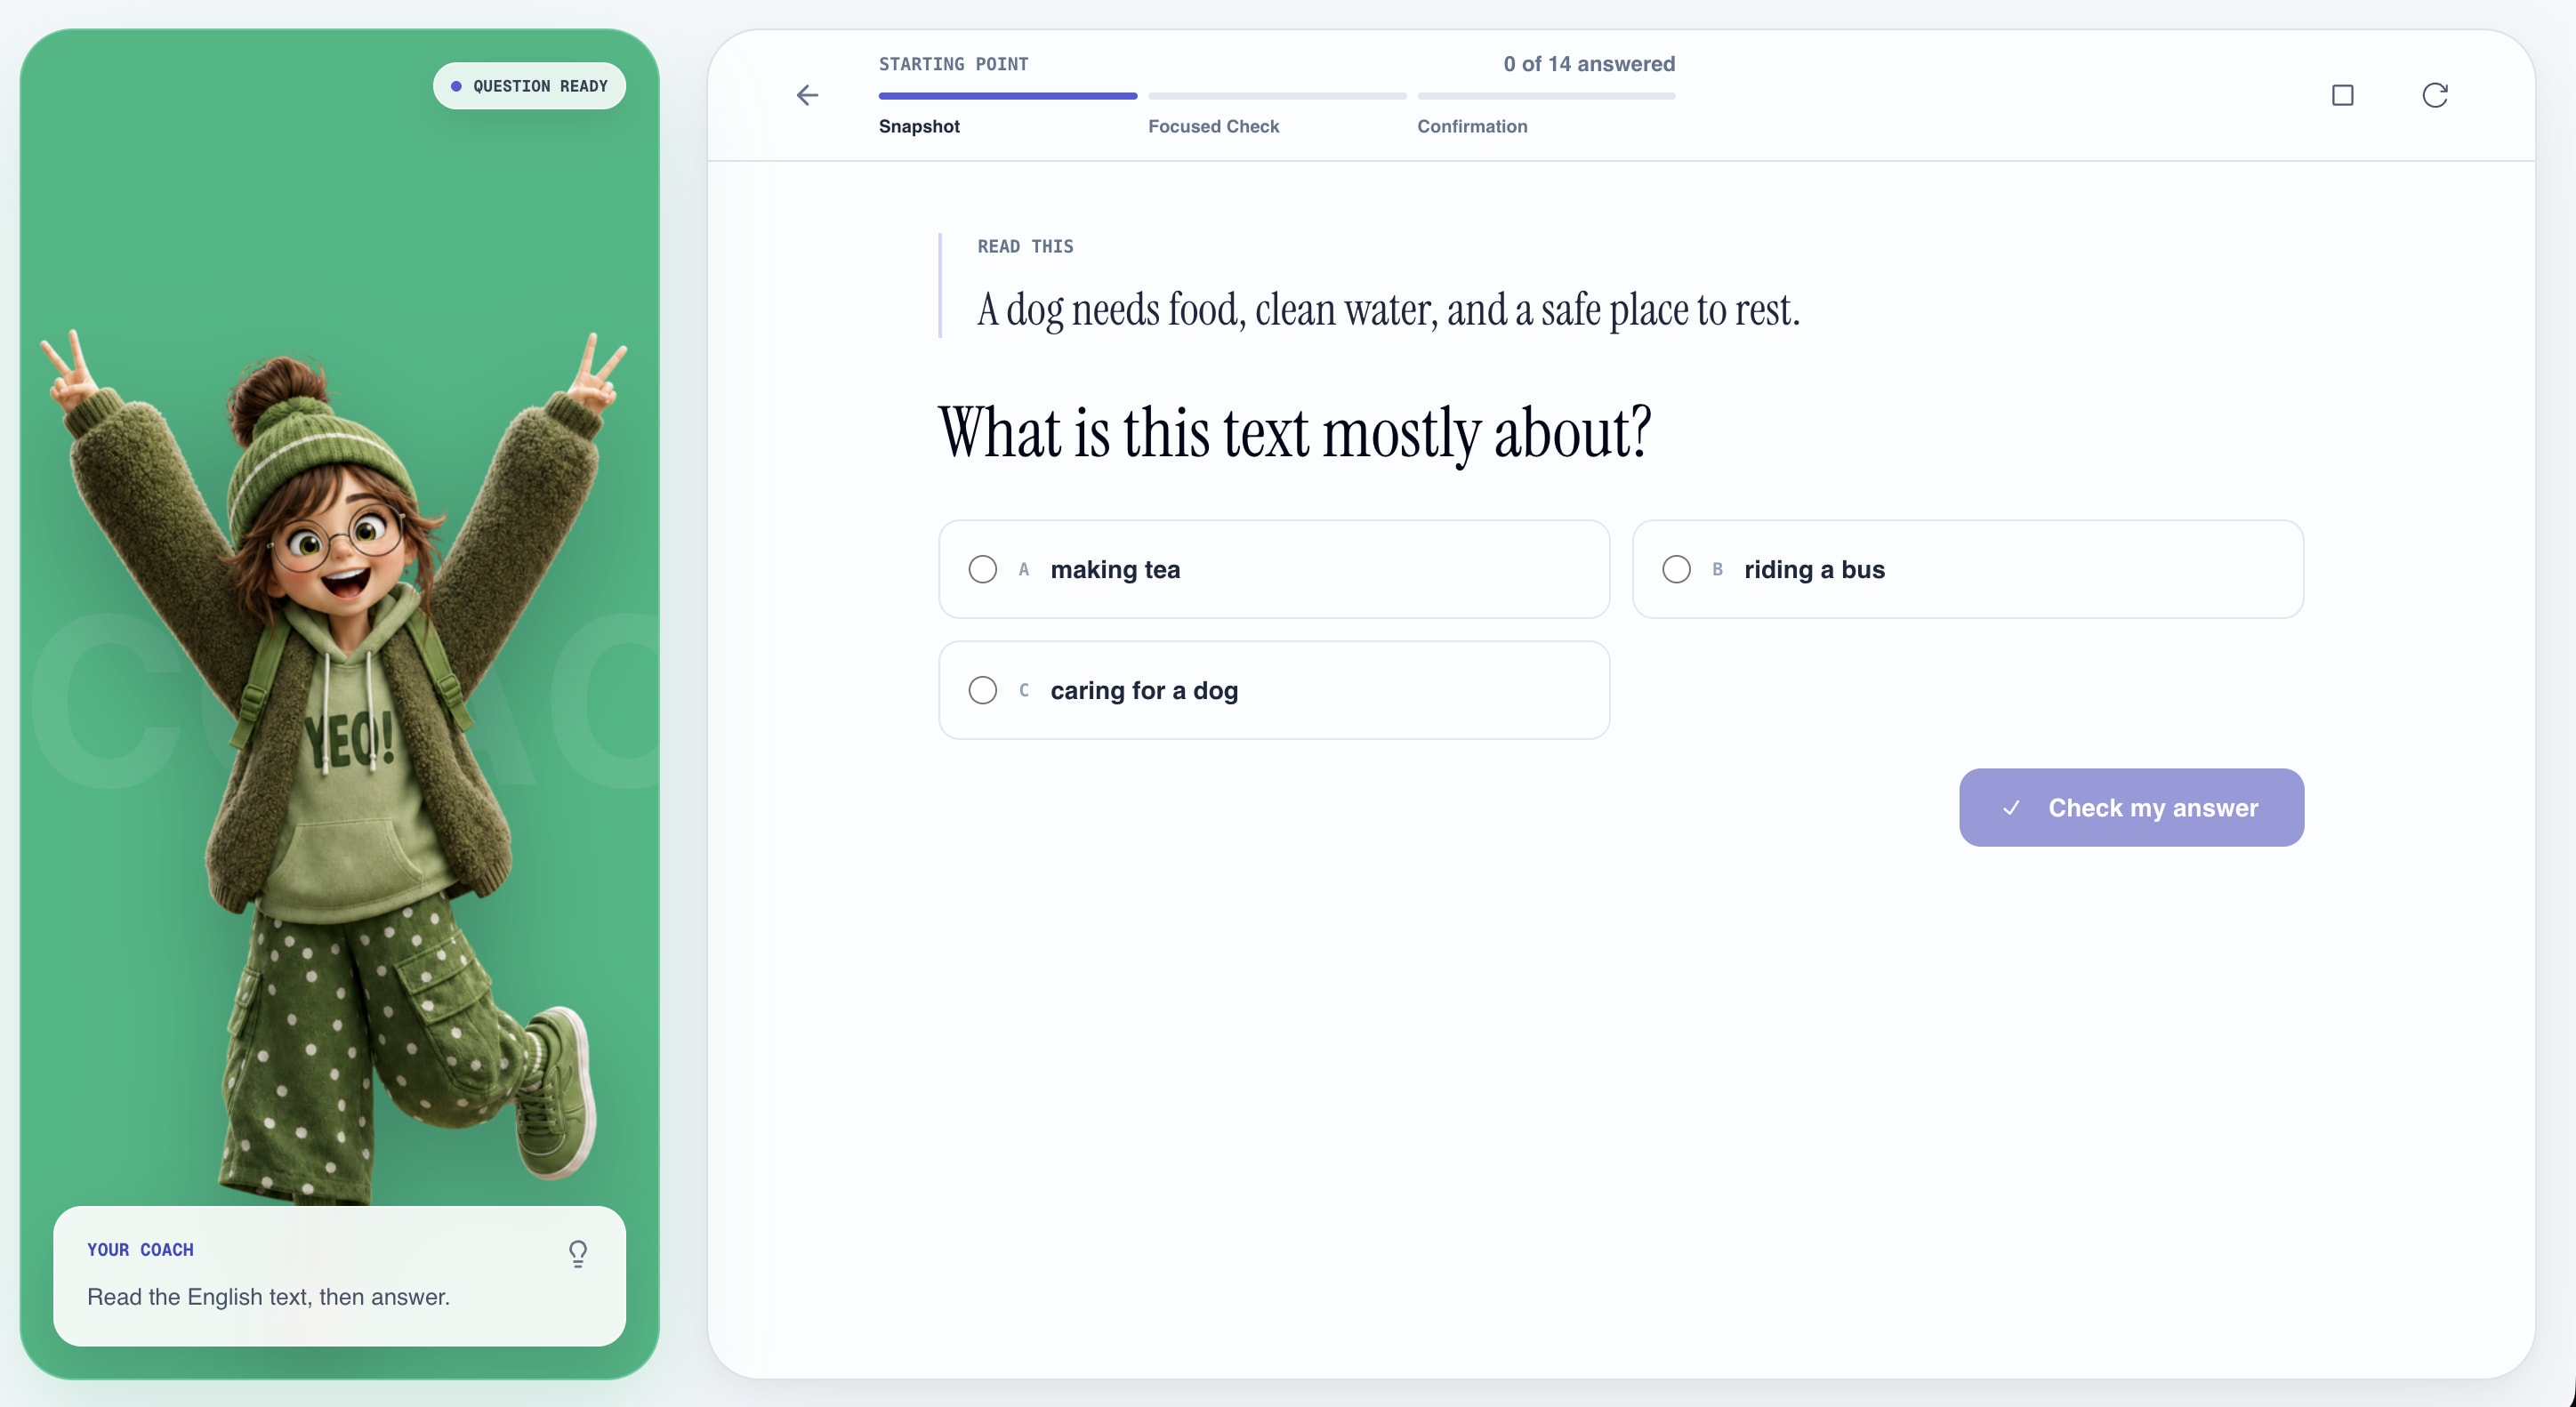
An AI English coach for learners in India, from Class 2 chapters to the interview room.
 Video
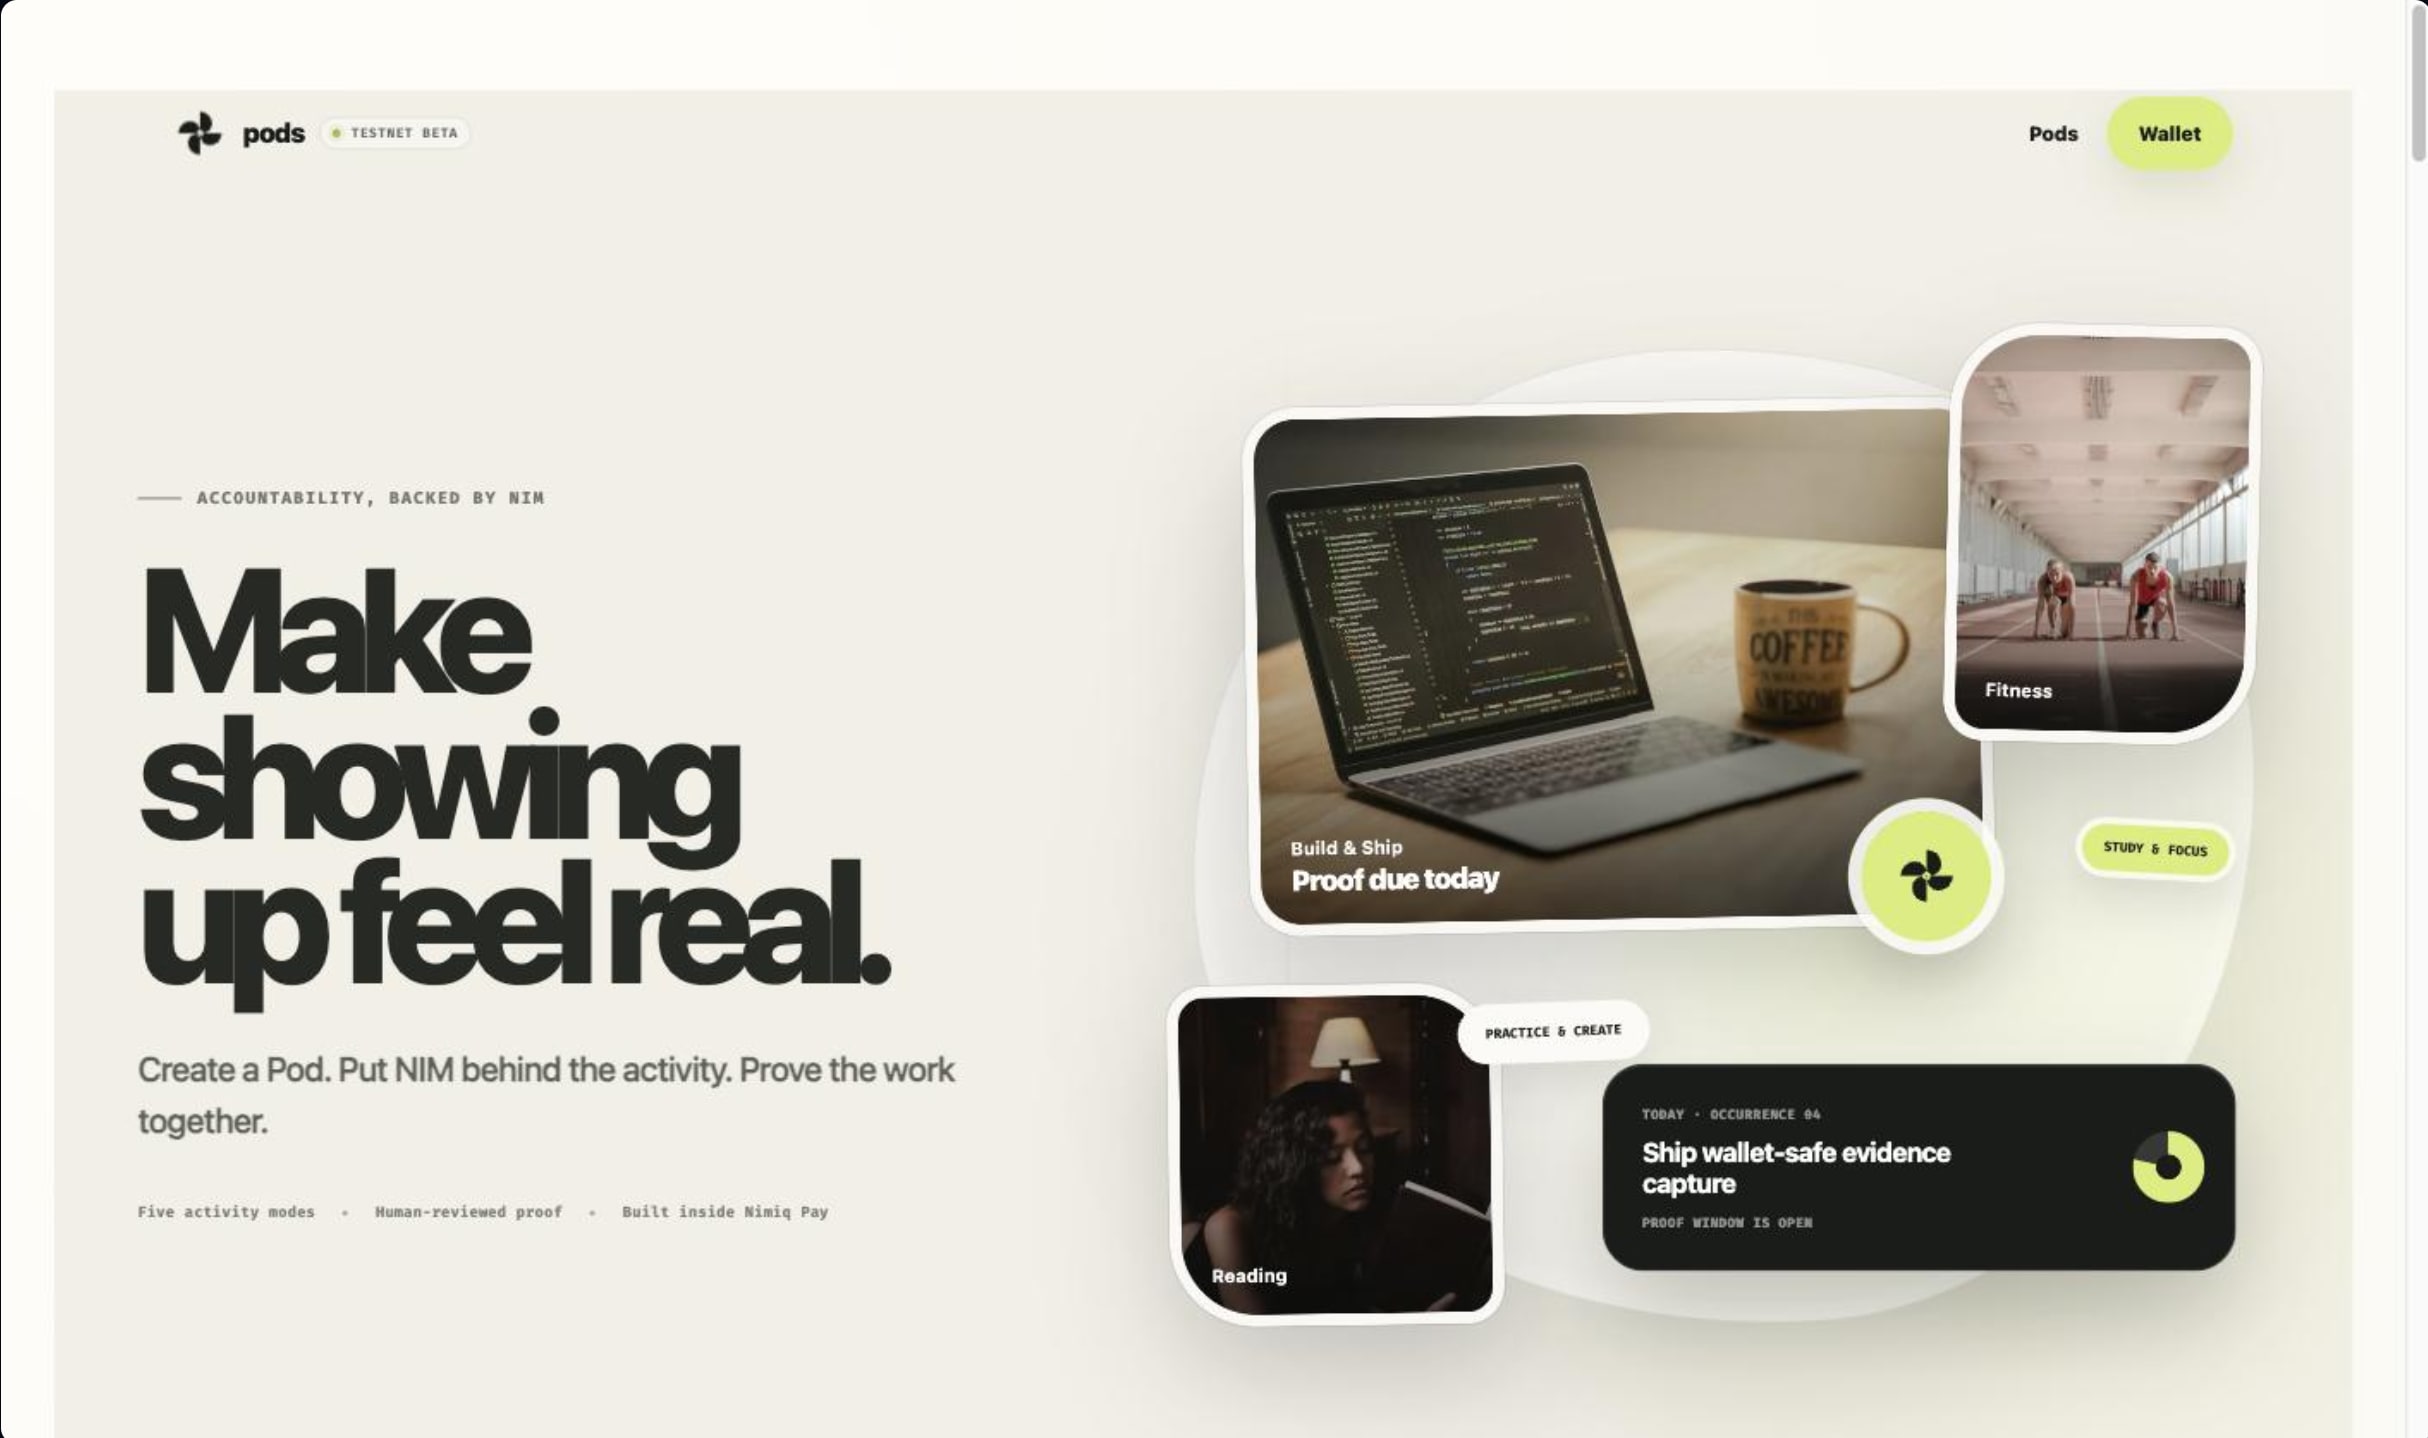
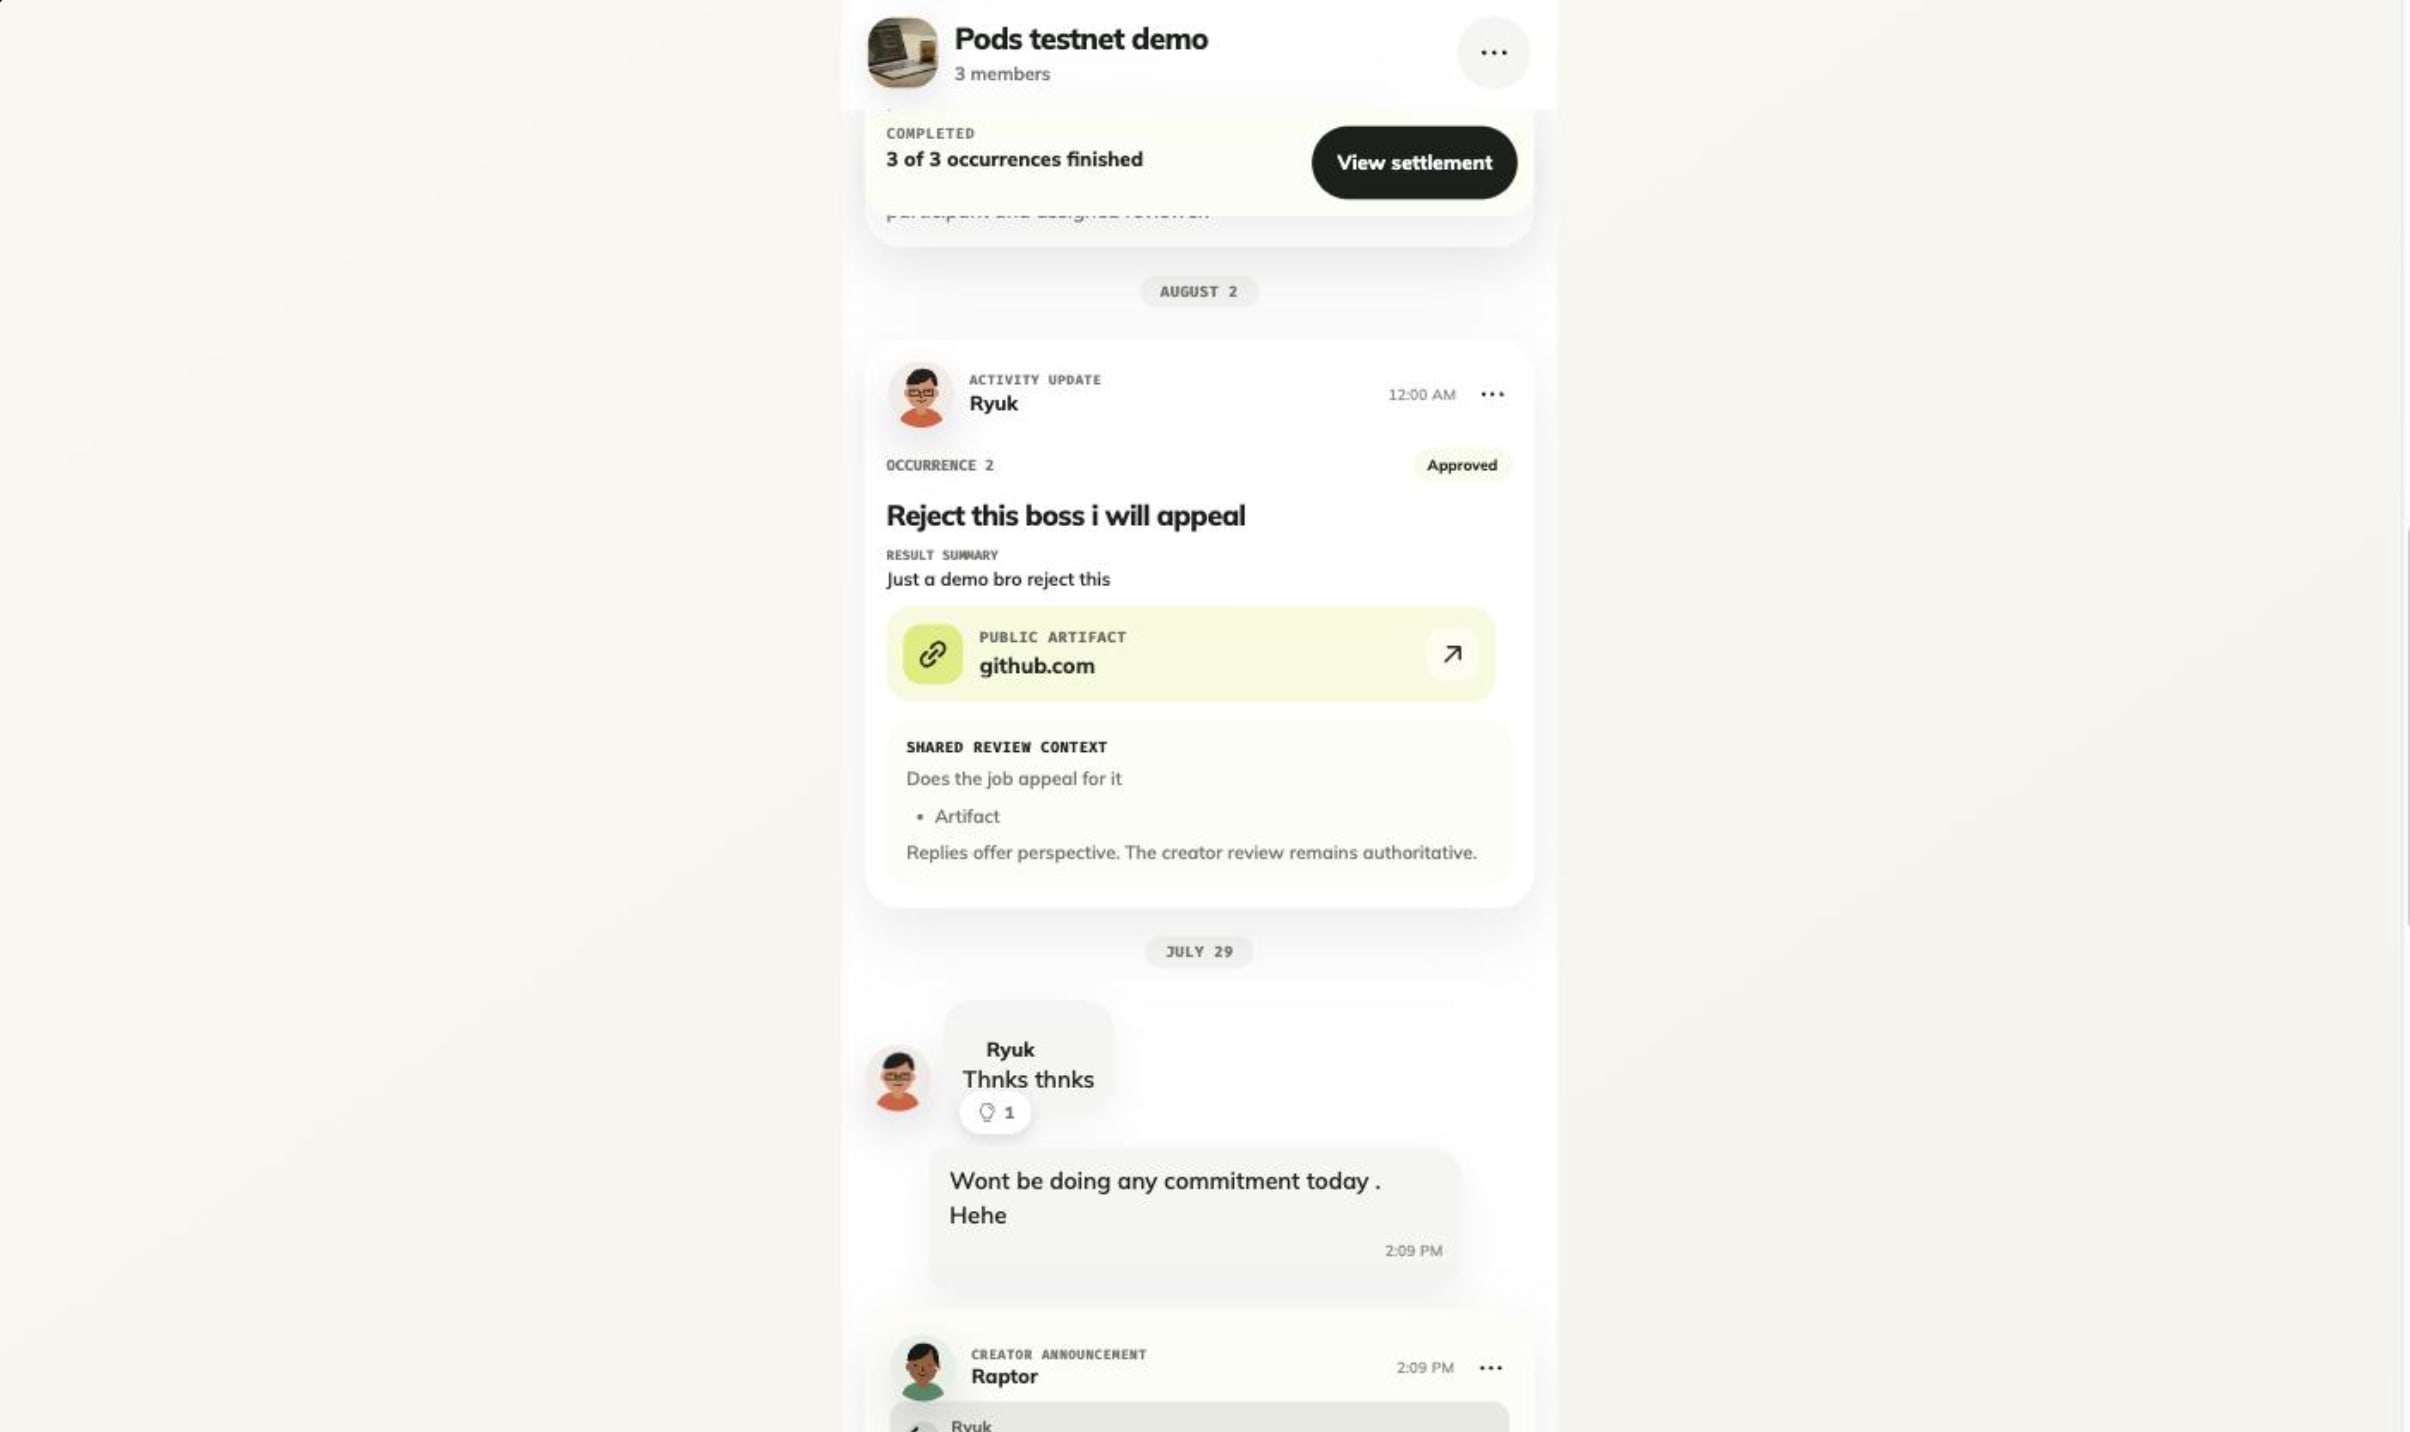
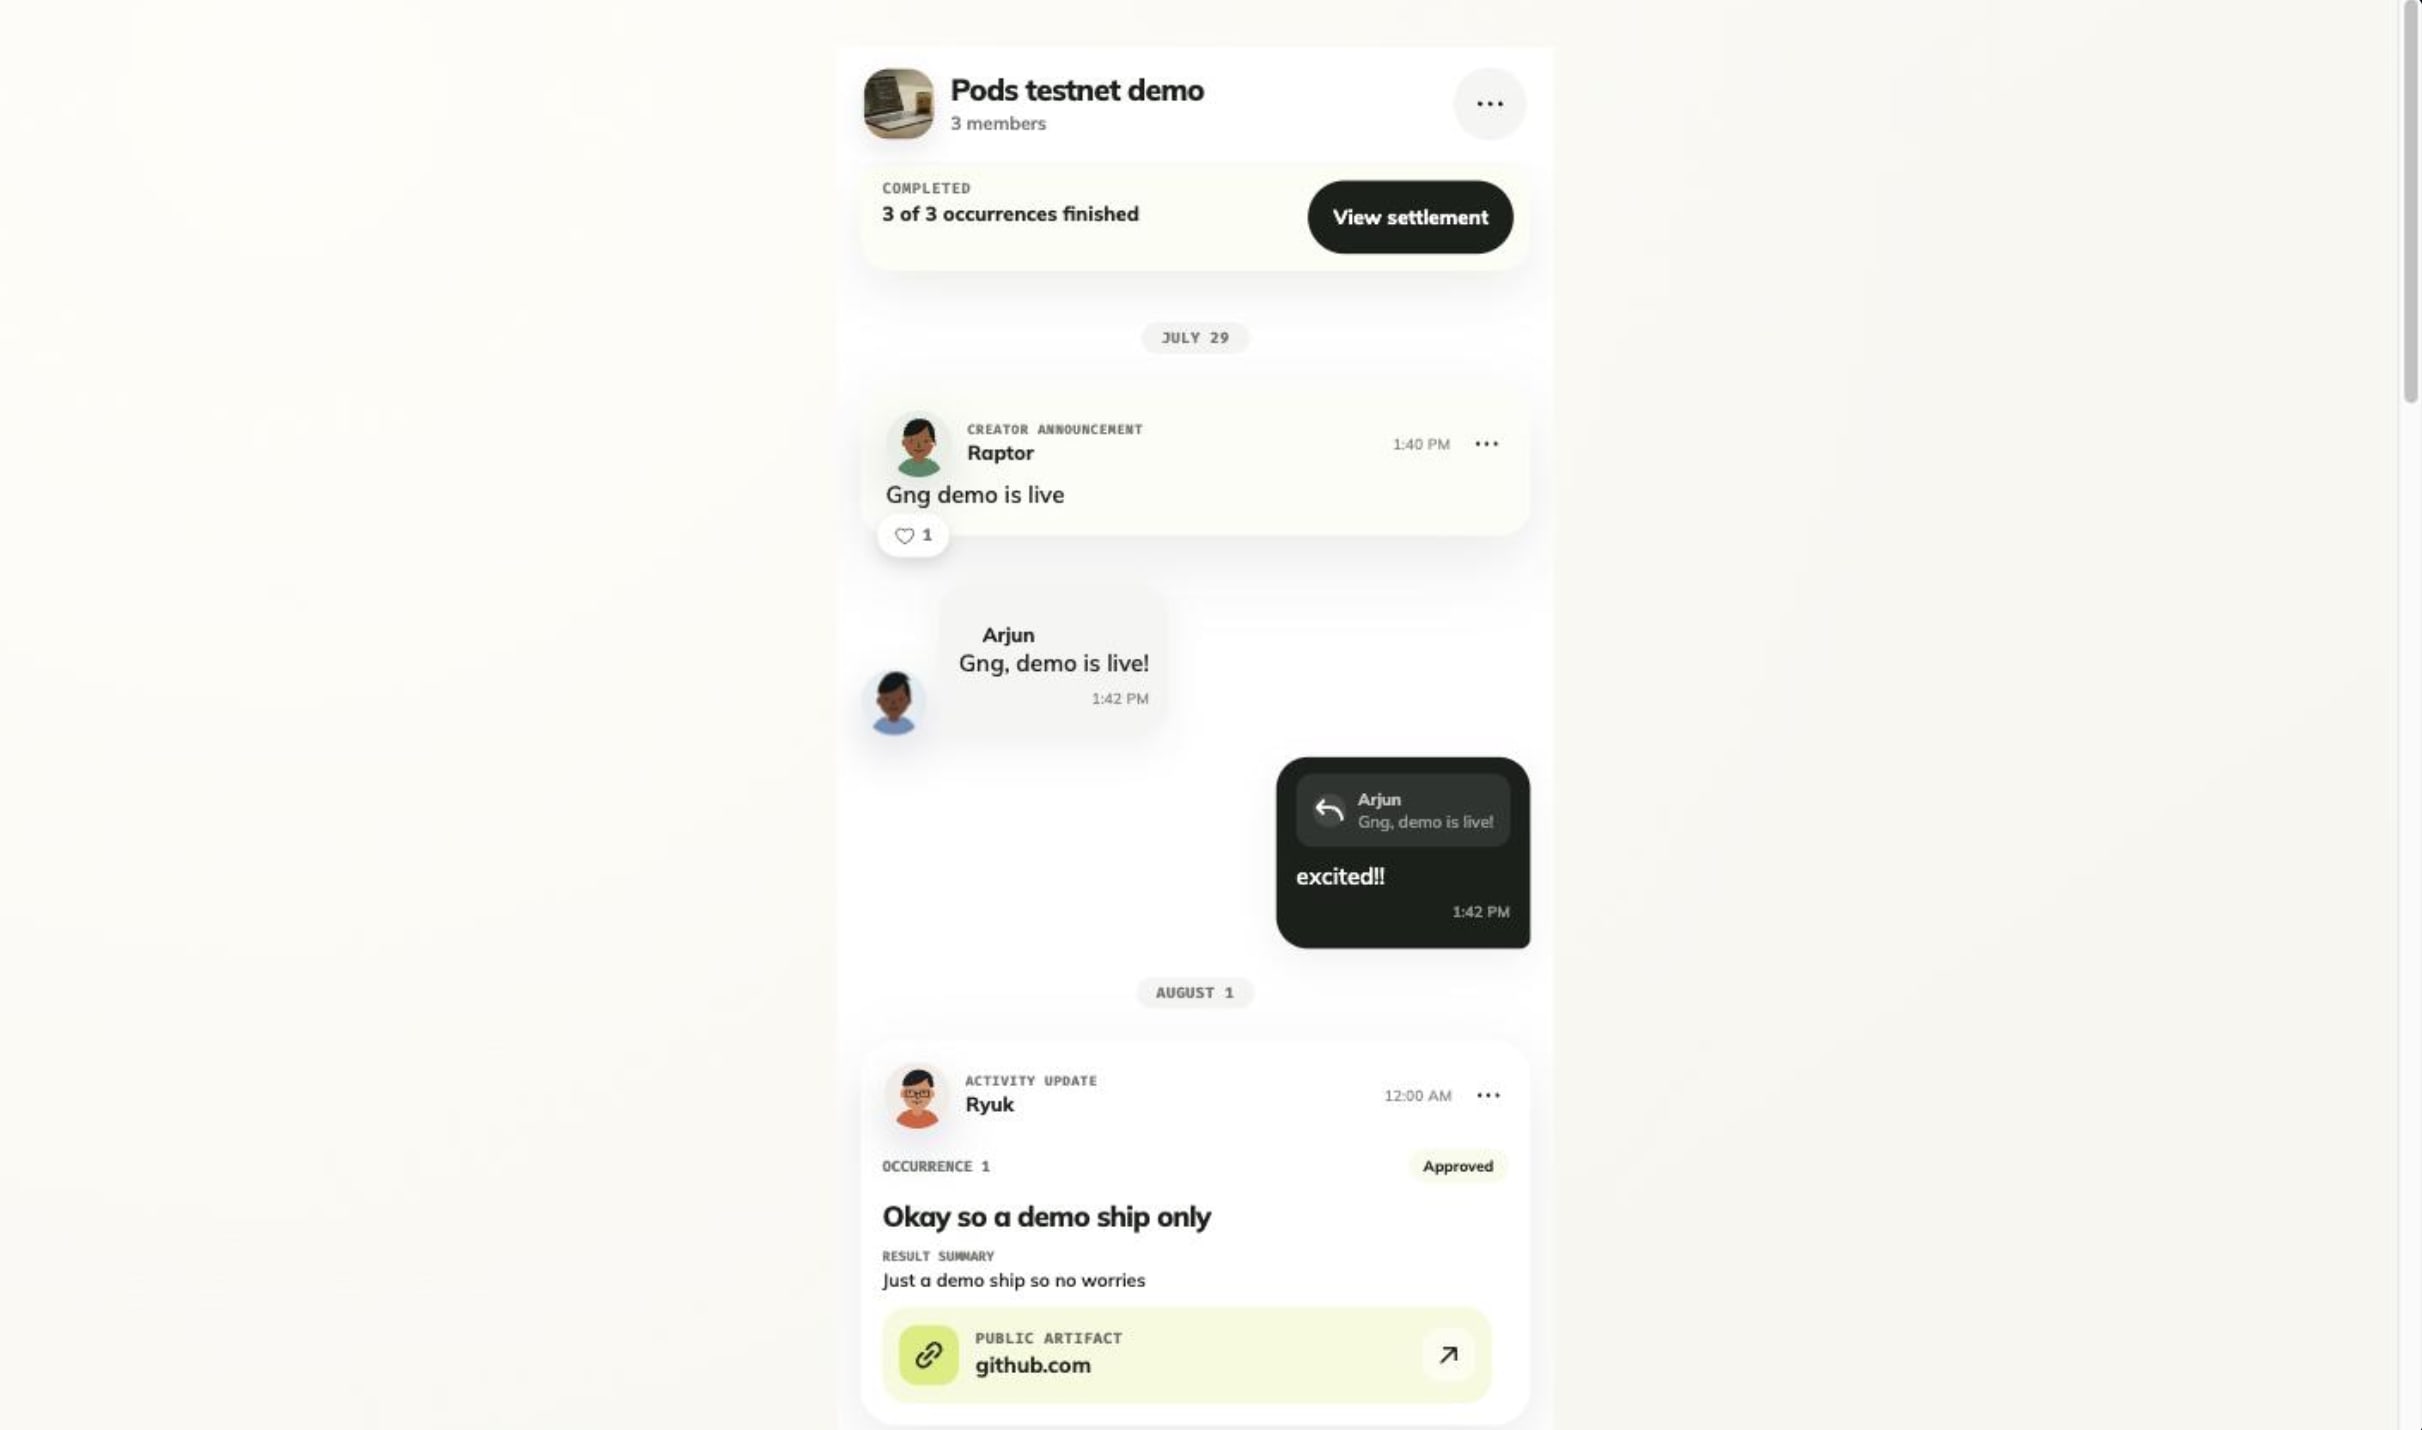
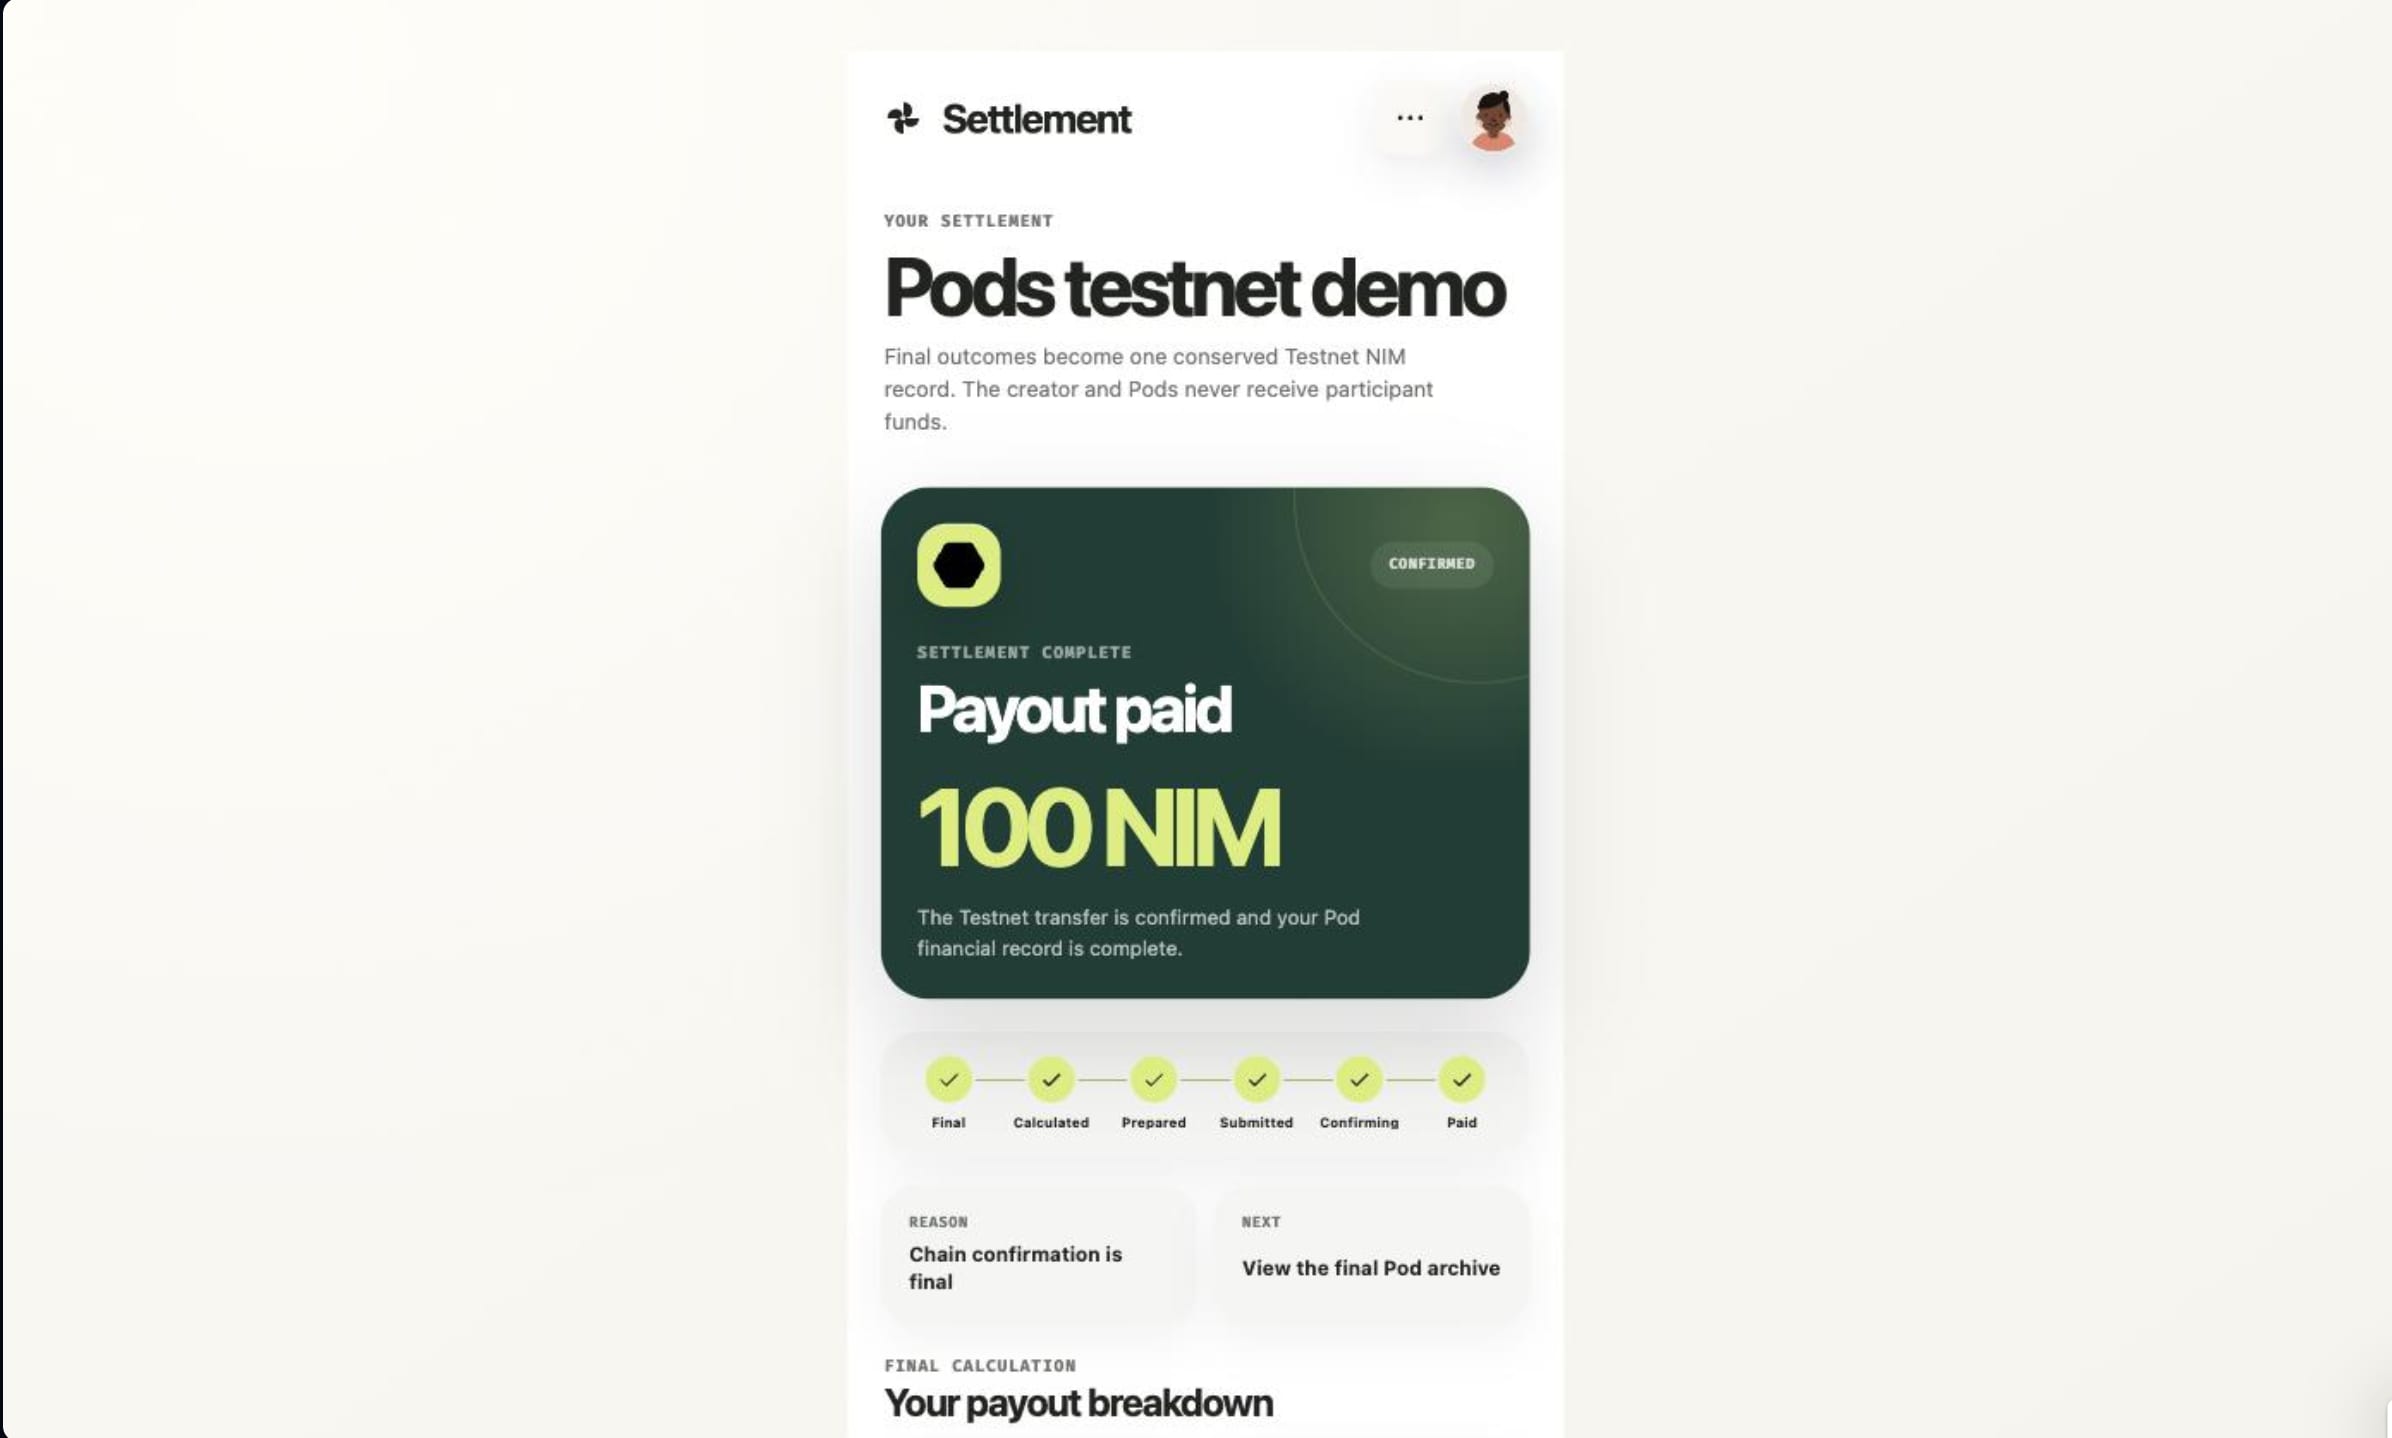
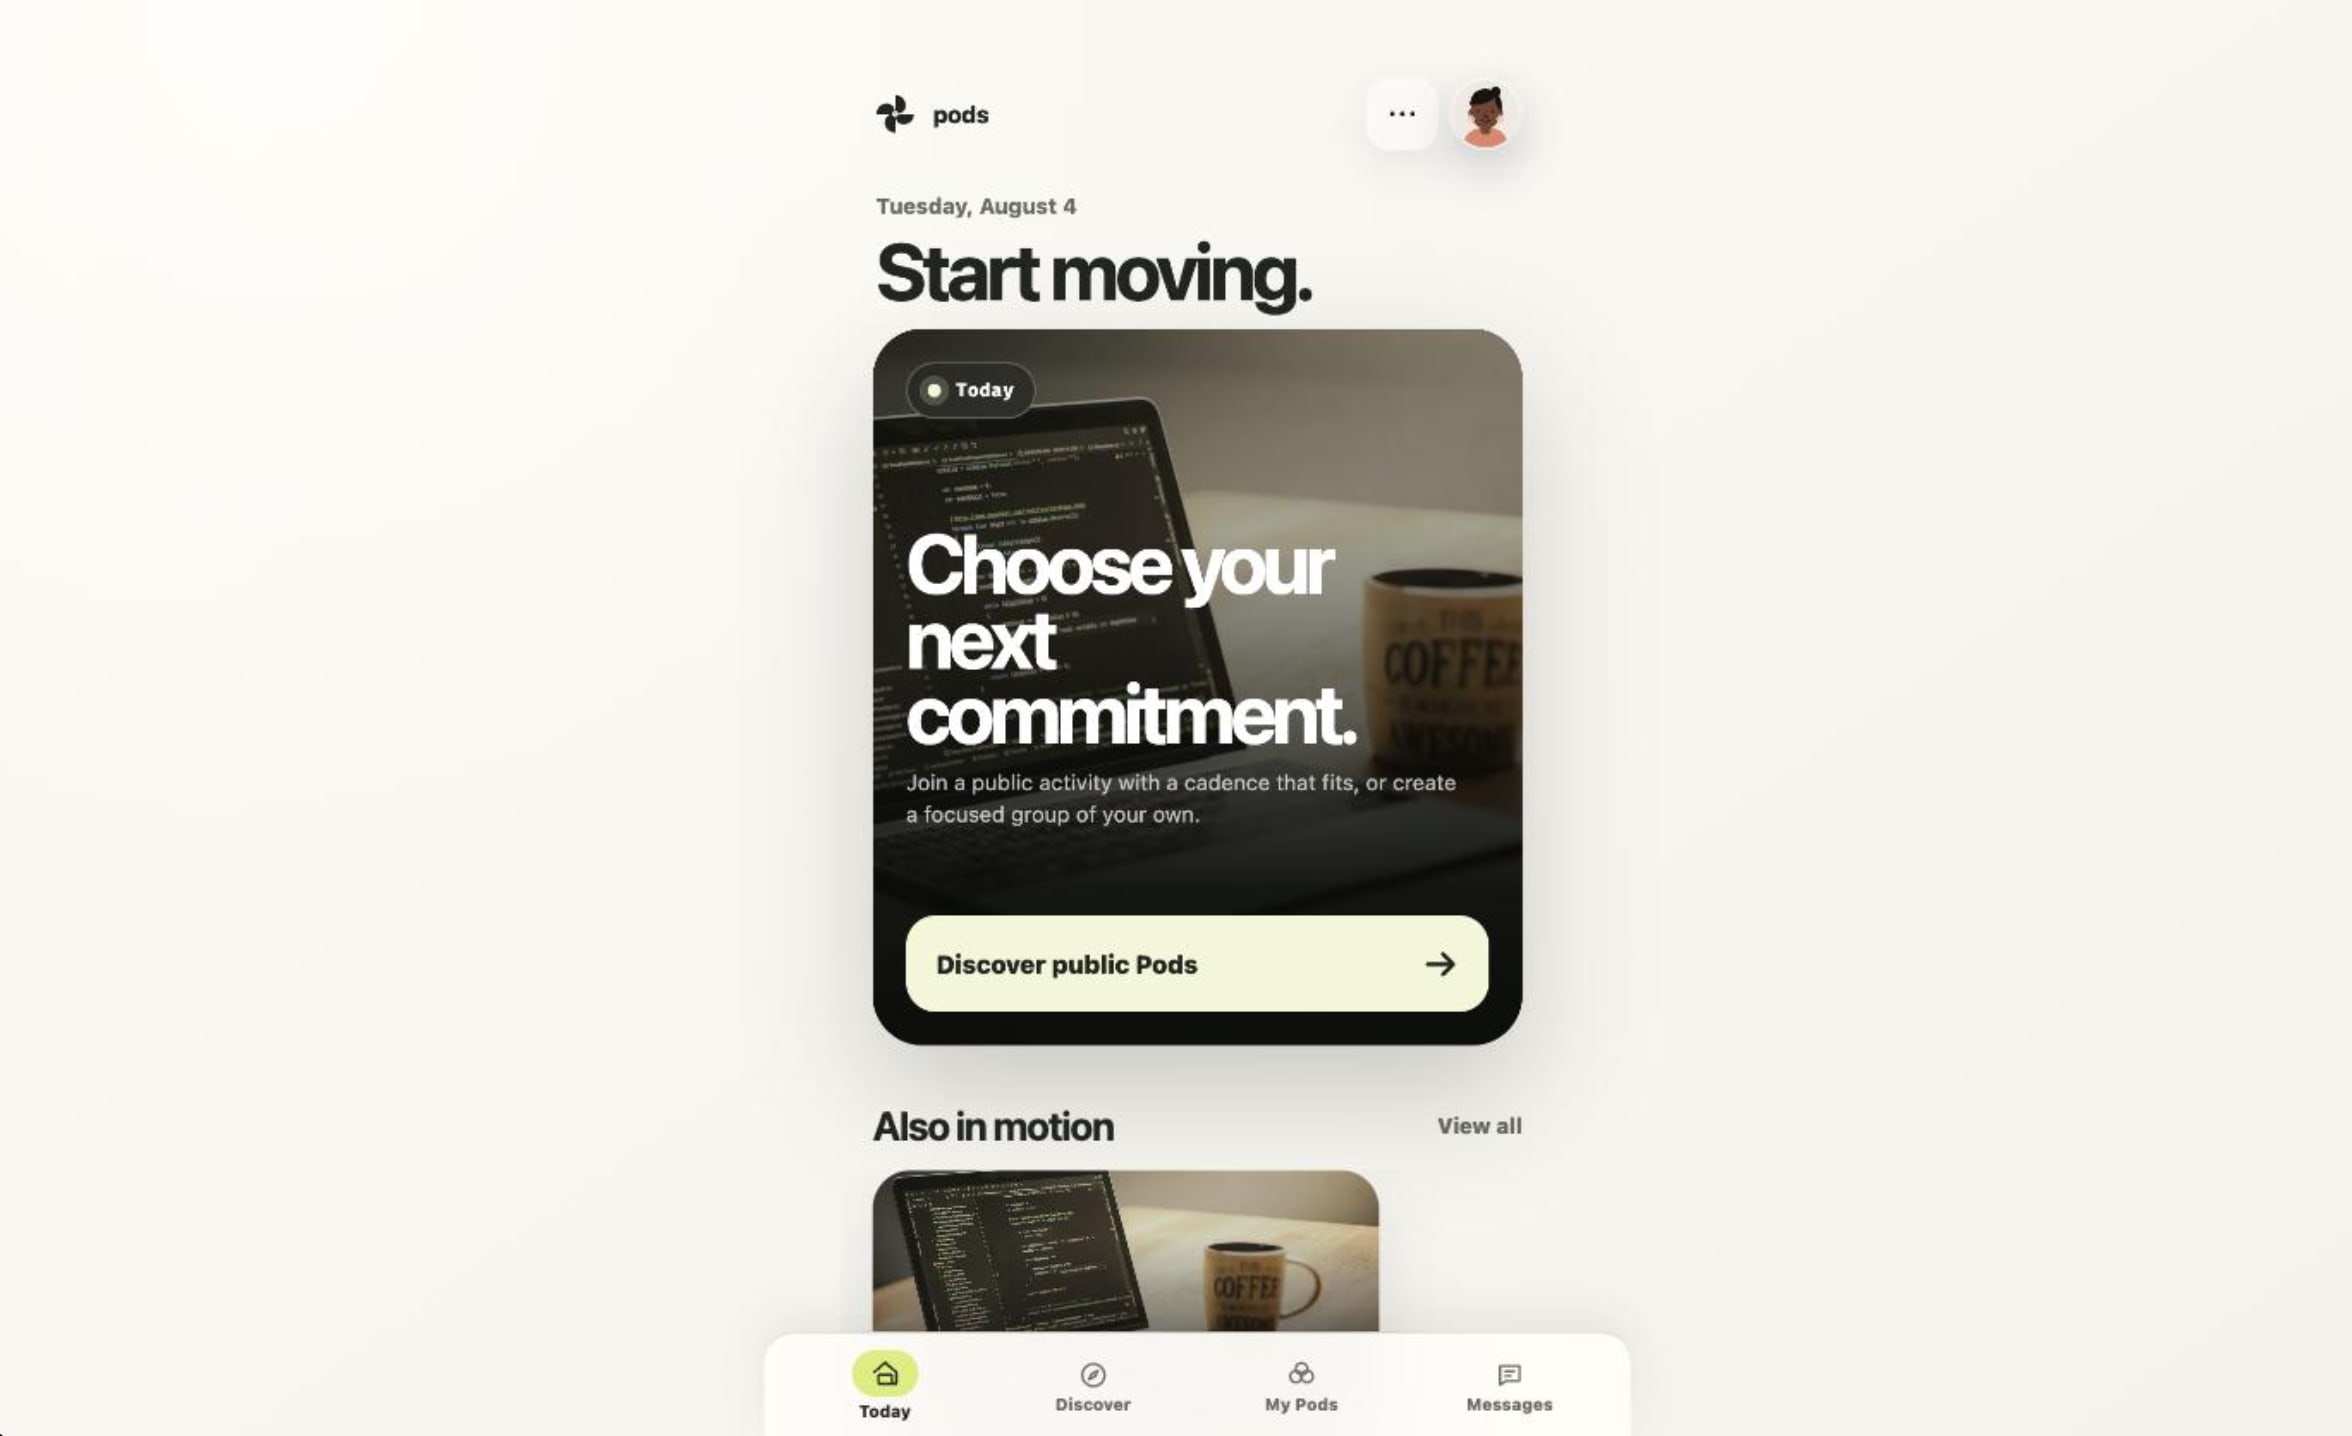
An accountability platform for small groups, rebuilt in C# on .NET 8.
 Video
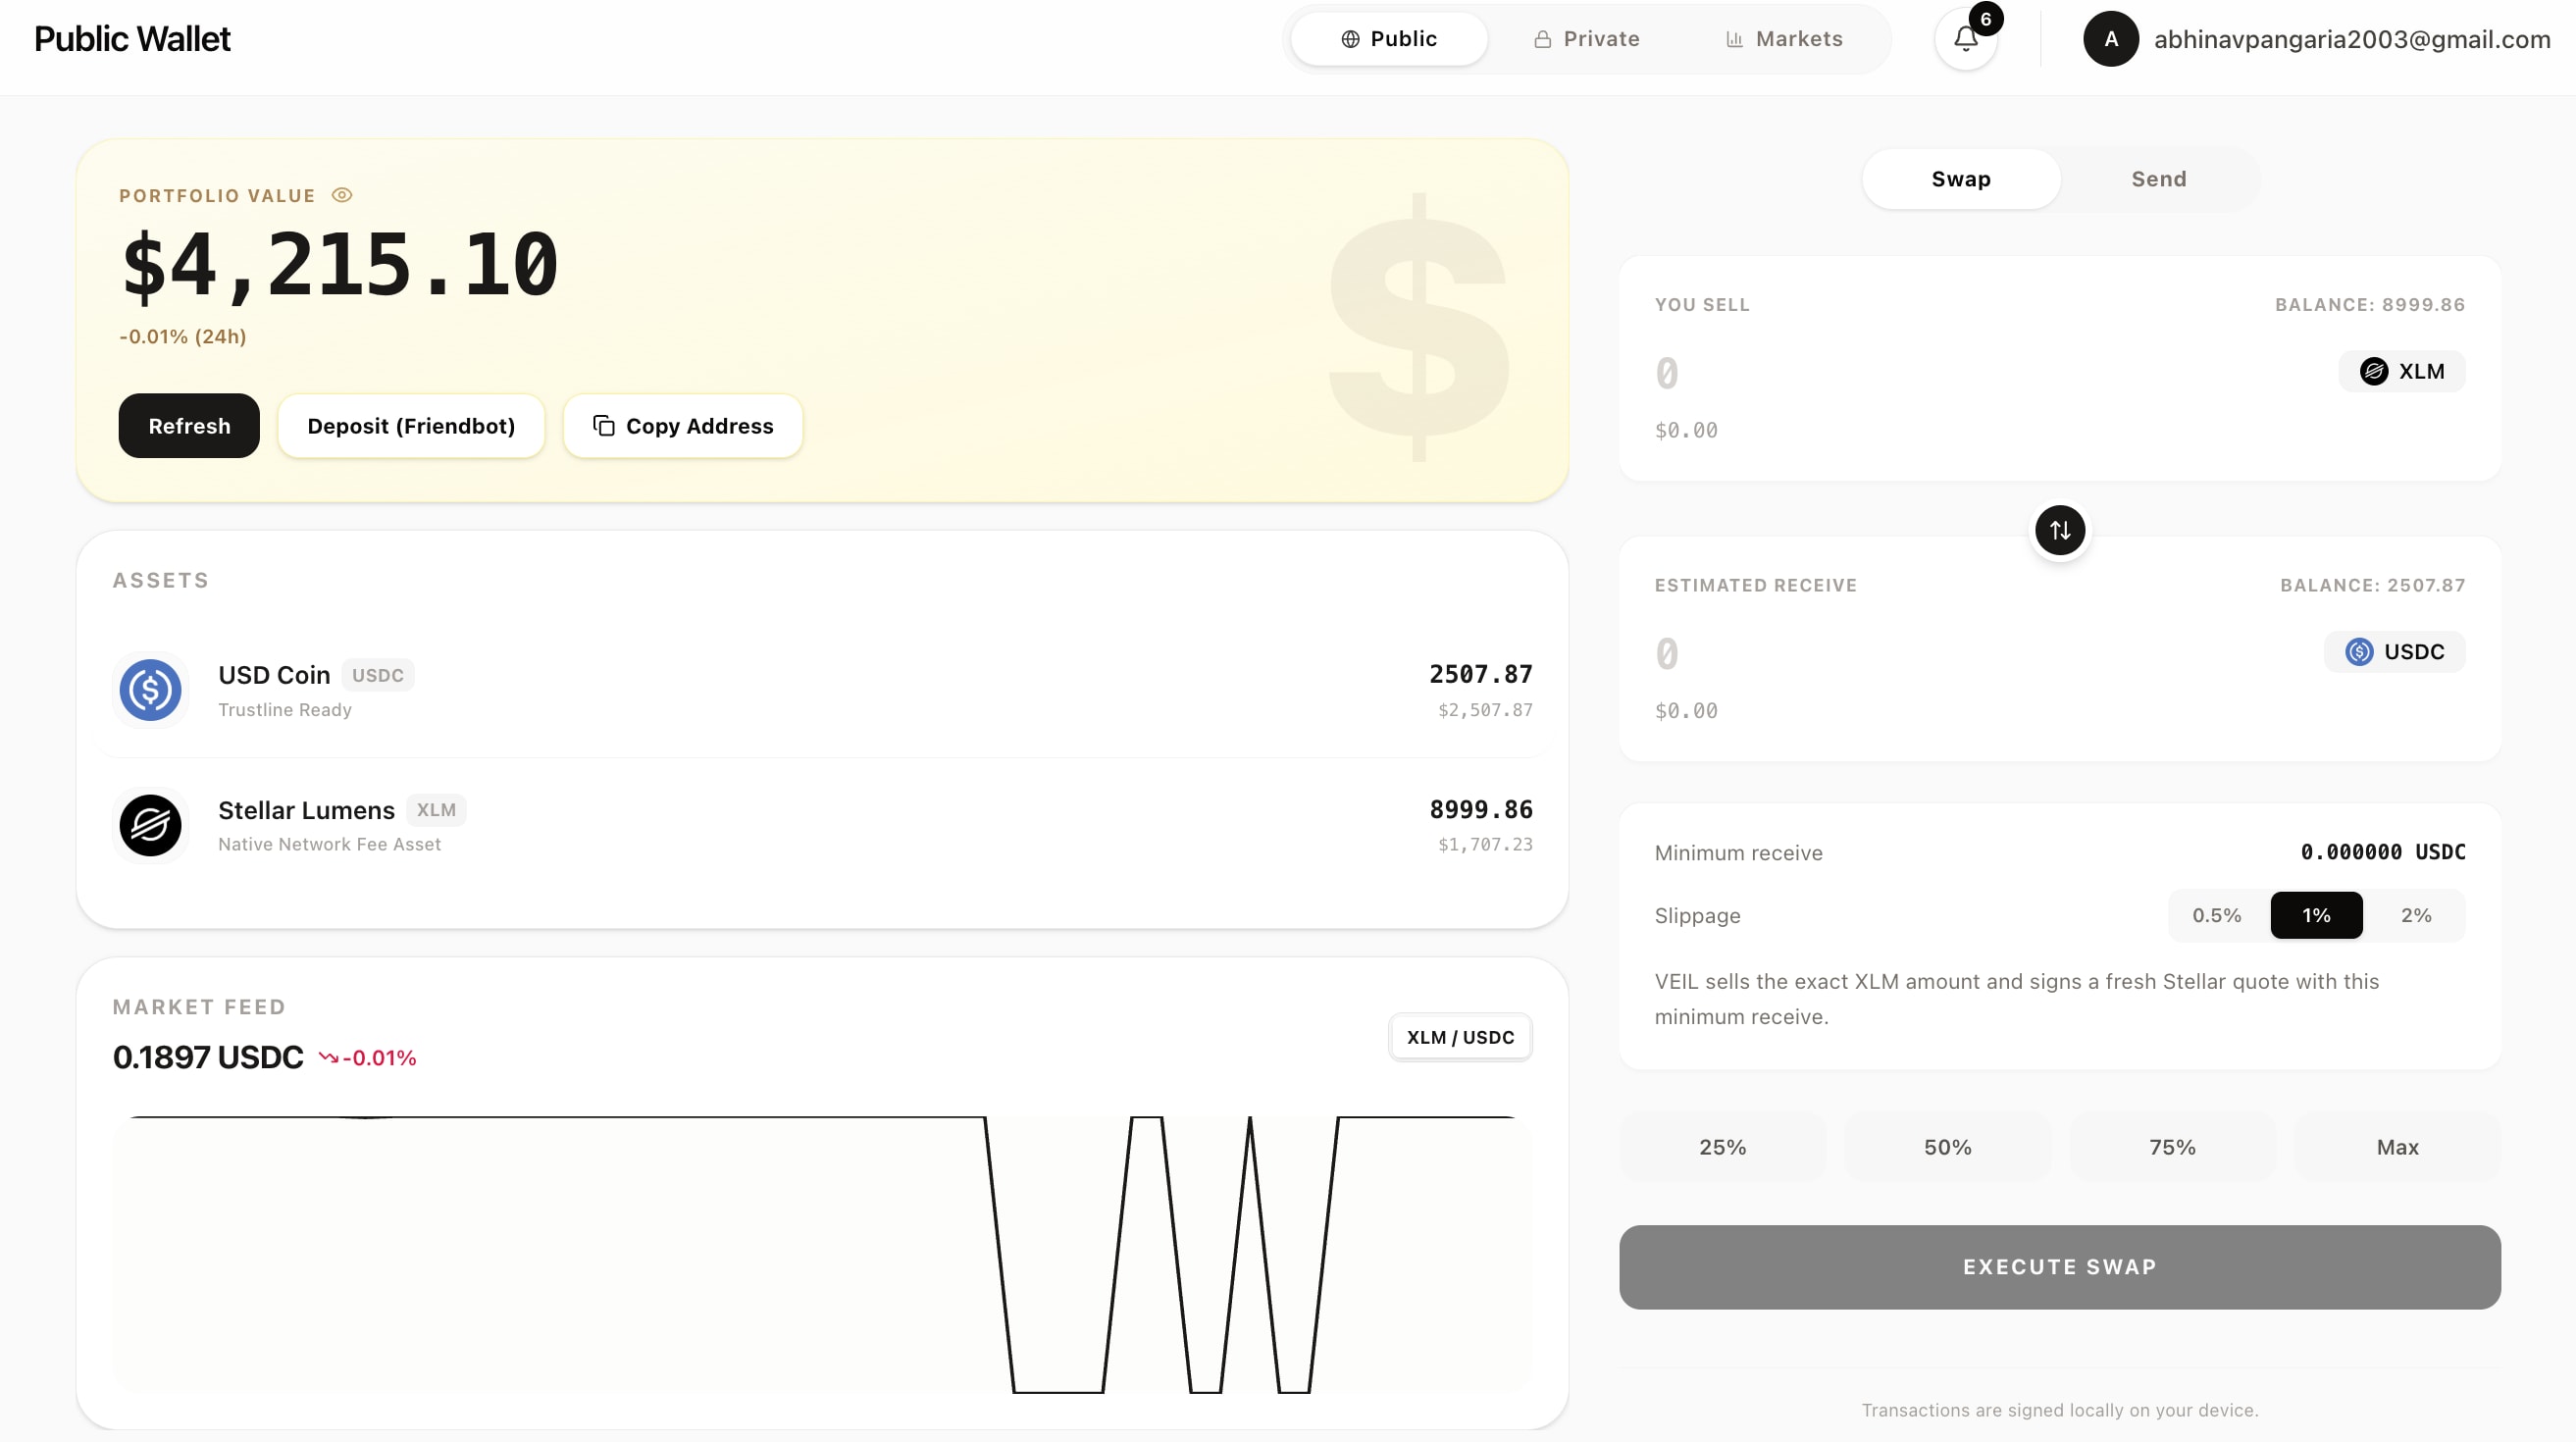
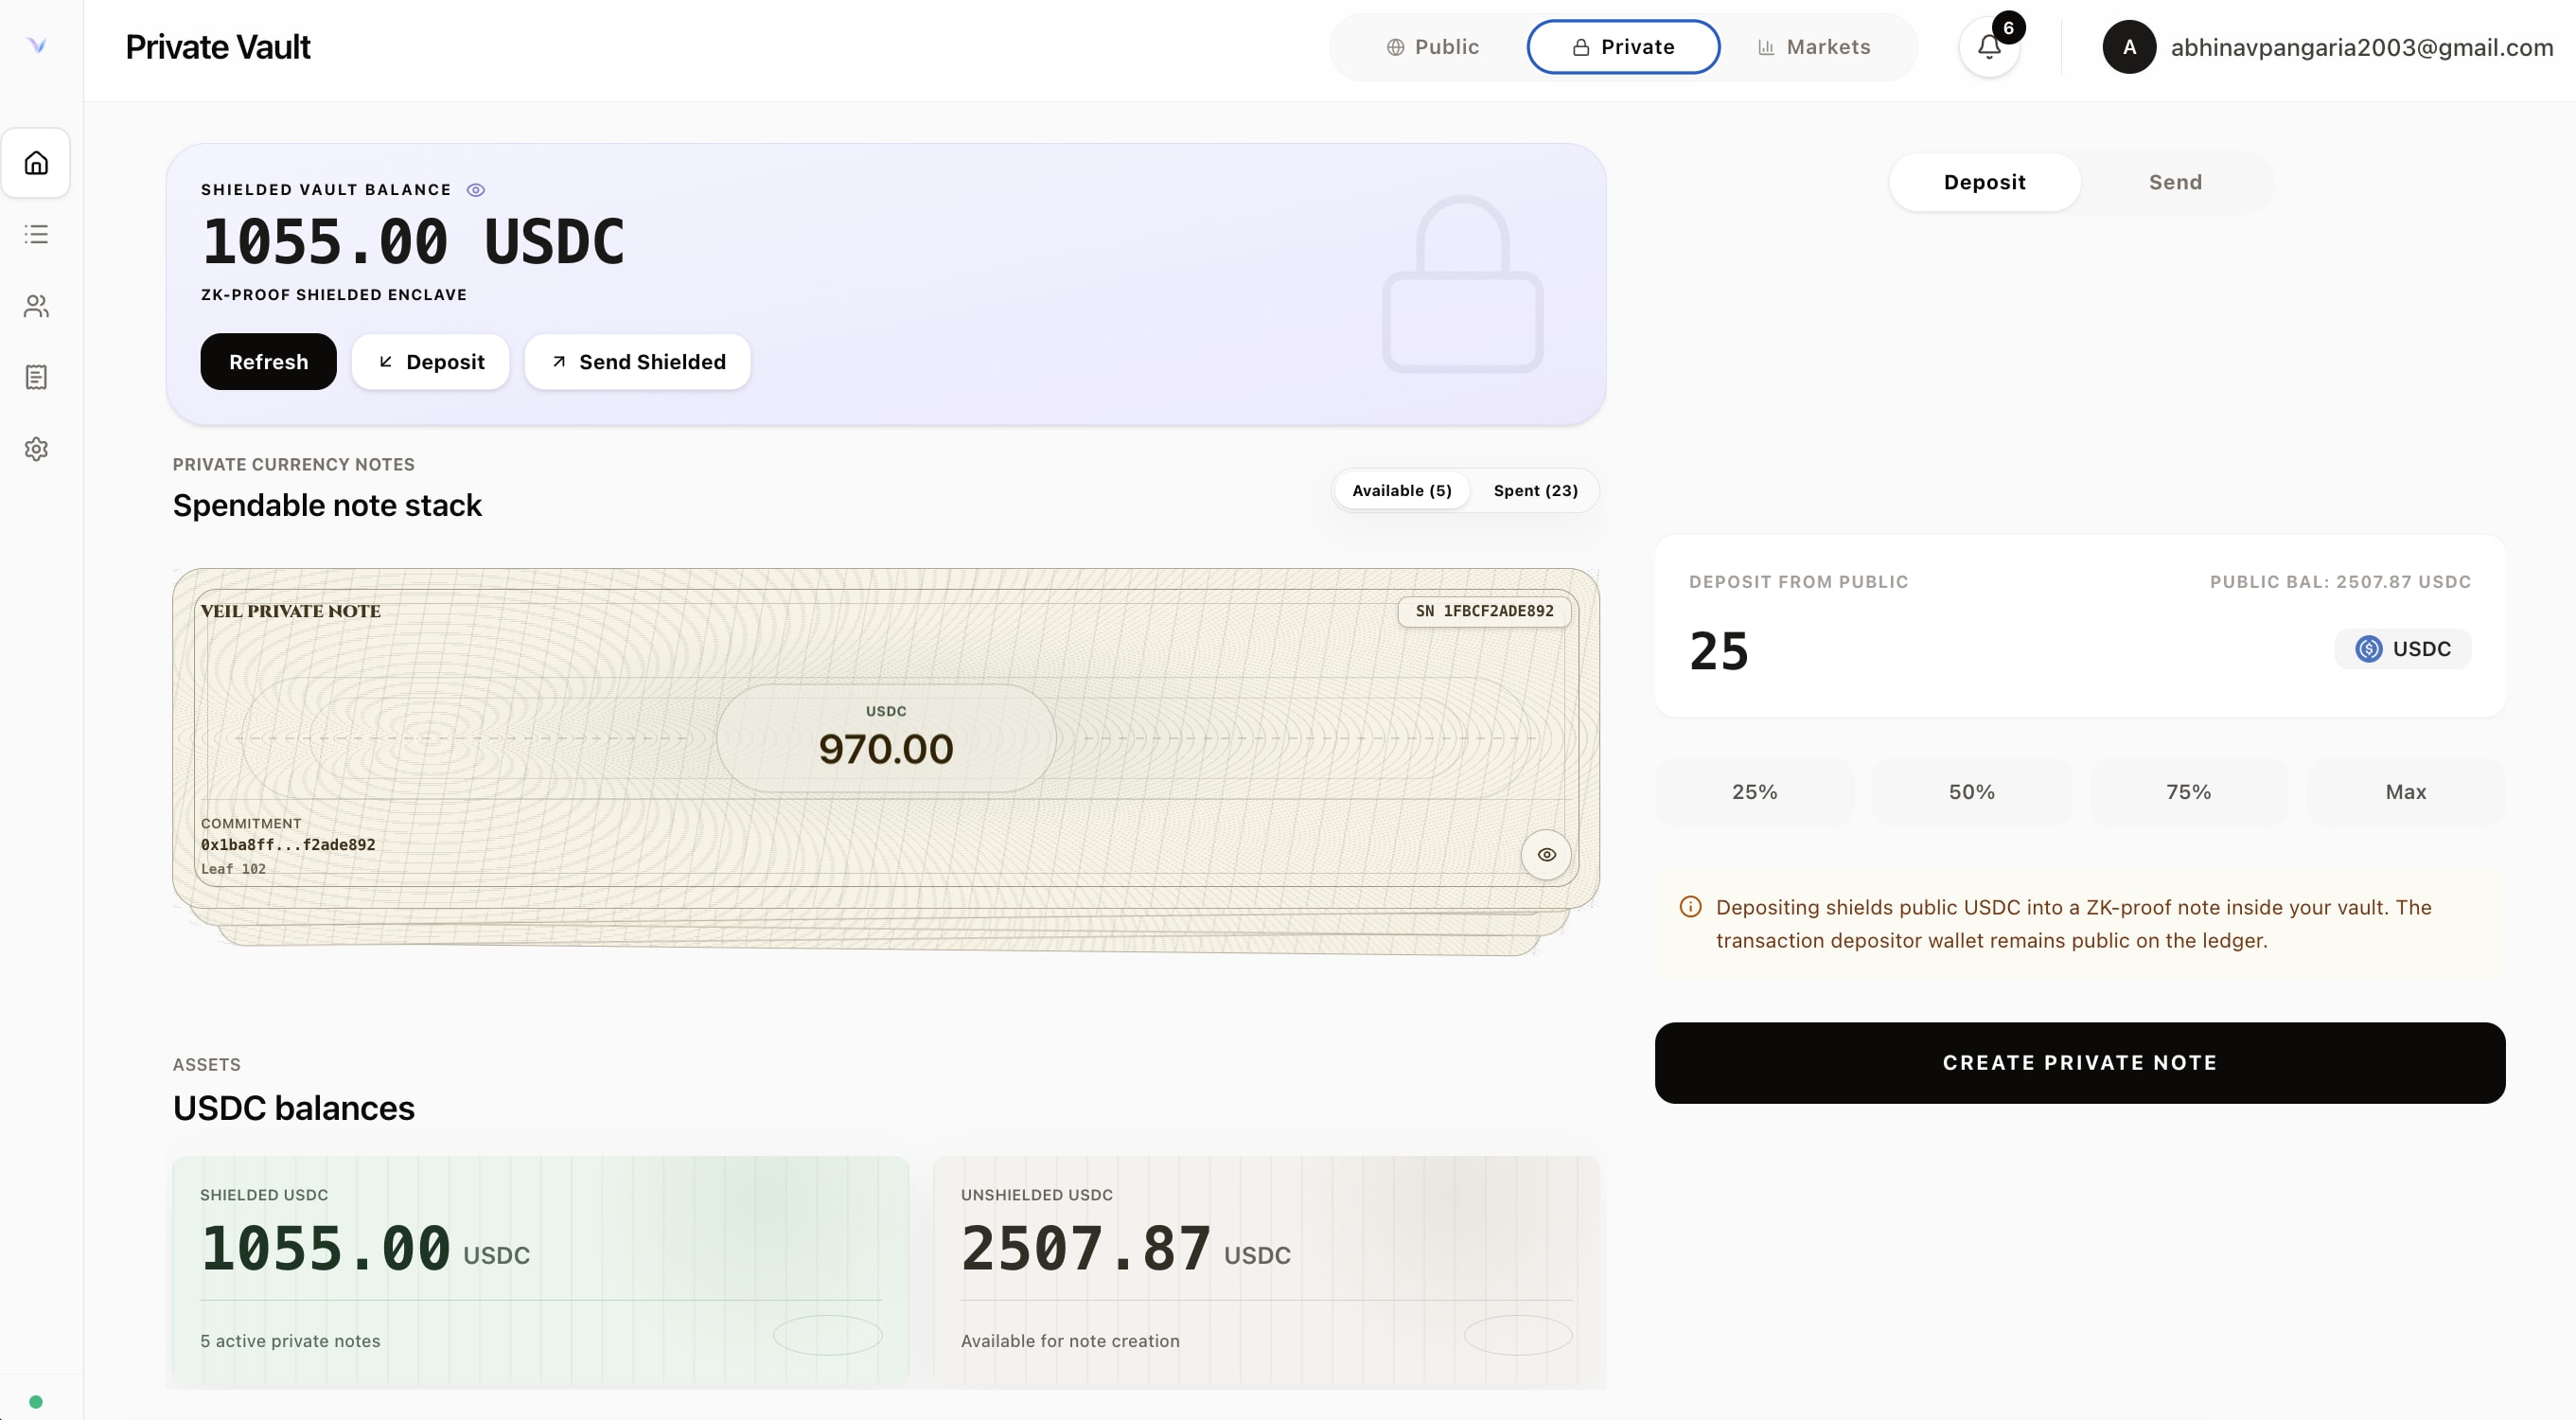
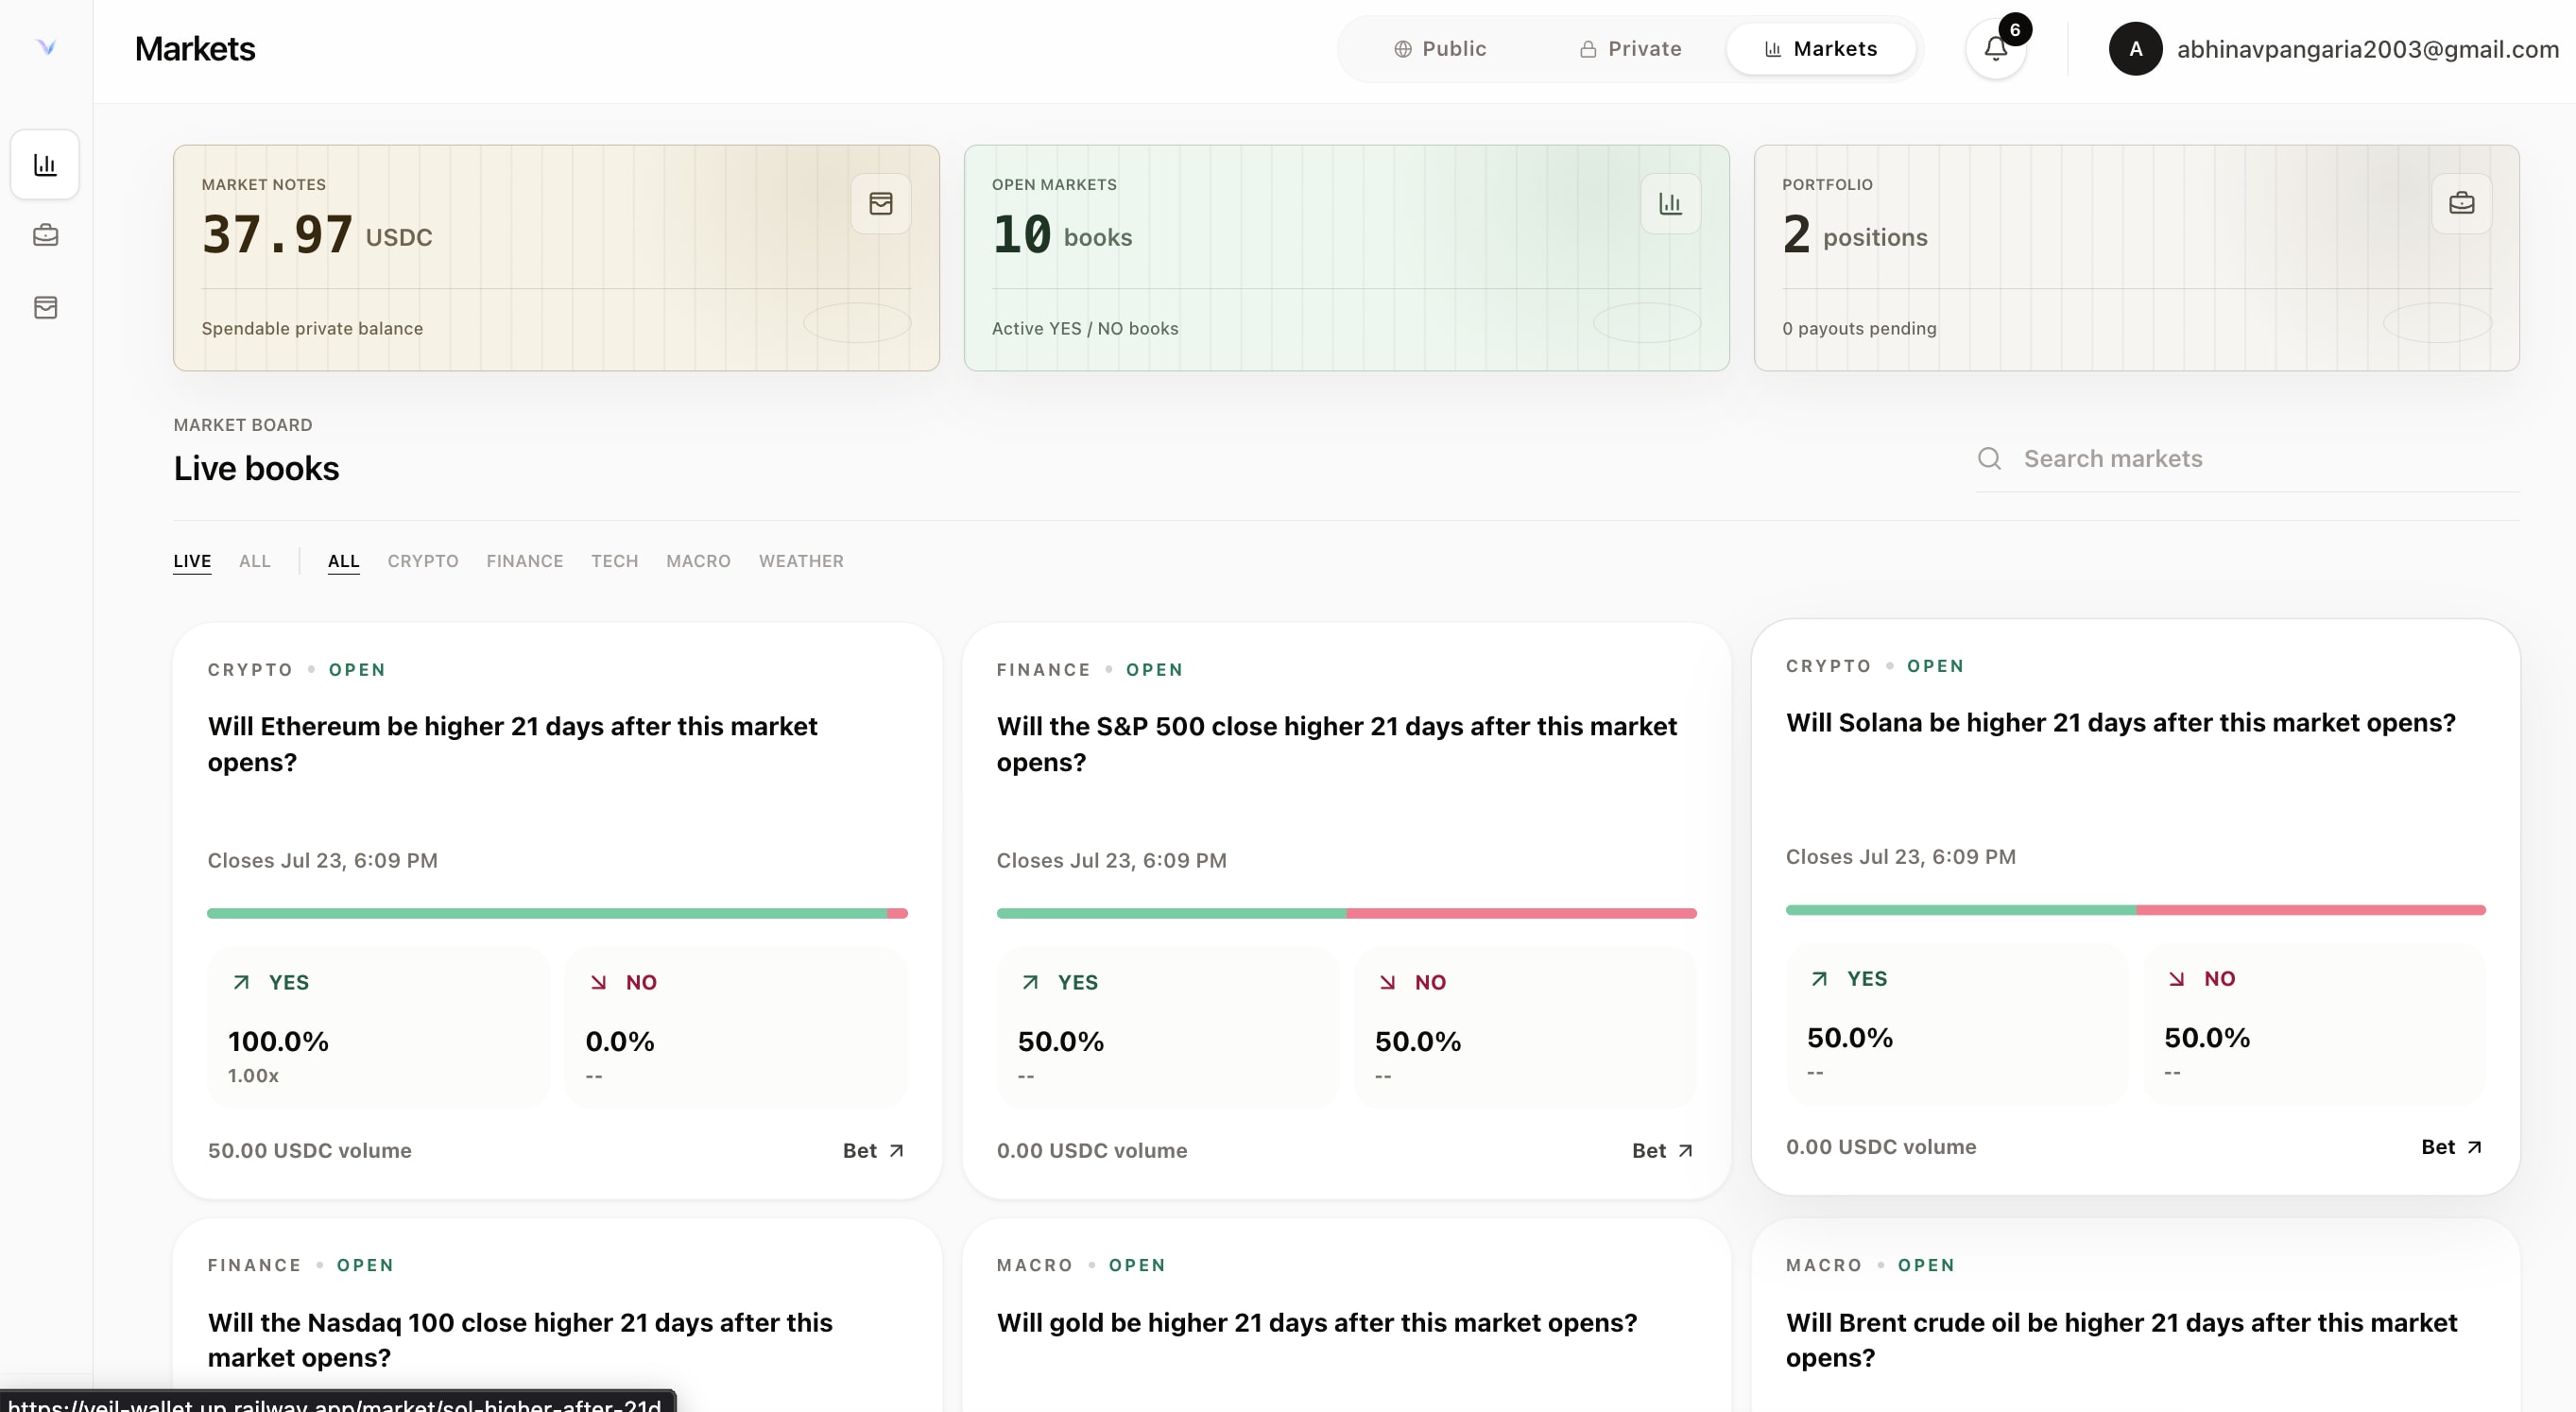
Privacy as a wallet primitive. Shielded notes, private sends, and prediction markets on Stellar.


 Video
DeFi with memory. Polkadot's on-chain credit layer.


 Video
The Mantle-native gateway bridging the RWA liquidity gap.


 Video
Cross-border payroll and treasury, built for crypto-native teams.


Privacy-preserving payment & identity mixing on Stellar.
Local inference vs. the browser compositor: why GPU-heavy pages stutter while a model reads.
Independent research on one sentence from Dart's DBR-2026-05: a model that starves the compositor makes a janky browser. On a MacBook Pro (M4 Pro, 24 GB) a harness records every page frame next to every inference phase on one clock, 717 trials stored in SQLite. While a local 7B model prefills a 4k-token prompt at llama.cpp's default batch of 512, a GPU-heavy page drops 64% of its frames; decode drops about 0%, and CPU-only inference drops 0.1%, so the GPU is the shared resource. Capping the prefill batch at 64 tokens takes that page to 1.3% (WebGL Aquarium from 83% to 0%) for 9 to 11% more time to first token, with a 3B or 7B model. Safari shows the same mechanism. The fix does not carry over to 14B, still 31% at batch 64, which suggests a base M1 or M2 running 7B behaves the same way. It also reruns Dart's published TTFT and memory claims, and lays out what I would do next.